2026
The Missing Primitive: Diagnosing and Repairing Mathematical Reasoning in Large Language Models
Shuo Xing, Zilin Dai, Chengyuan Qian, Fangzhou Lin, Wenjing Chen, Ping He, Pan Lu, Alvaro Velasquez, Mohit Bansal, Zhengzhong Tu
arXiv preprint 2026
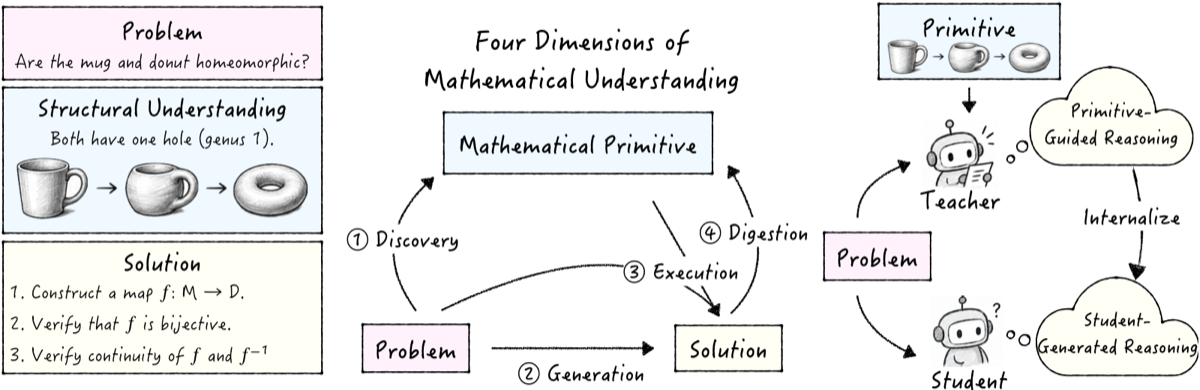
We take a first step toward systematically studying mathematical understanding in LLMs, from diagnosing its distinct capabilities to leveraging these findings to improve post-training. We introduce the notion of Mathematical Primitive to probe structural mathematical understanding and propose Prim, a benchmark that evaluates mathematical reasoning along four dimensions: Discovery, Generation, Digestion, and Execution. Our diagnosis shows that solution accuracy masks distinct capability profiles, primitives unlock substantial latent execution capacity, and Discovery is the dominant bottleneck. Building on these findings, we introduce Absorb, a primitive-privileged self-distillation framework that consistently improves mathematical reasoning across model scales and challenging benchmarks.
The Missing Primitive: Diagnosing and Repairing Mathematical Reasoning in Large Language Models
Shuo Xing, Zilin Dai, Chengyuan Qian, Fangzhou Lin, Wenjing Chen, Ping He, Pan Lu, Alvaro Velasquez, Mohit Bansal, Zhengzhong Tu
arXiv preprint 2026
We take a first step toward systematically studying mathematical understanding in LLMs, from diagnosing its distinct capabilities to leveraging these findings to improve post-training. We introduce the notion of Mathematical Primitive to probe structural mathematical understanding and propose Prim, a benchmark that evaluates mathematical reasoning along four dimensions: Discovery, Generation, Digestion, and Execution. Our diagnosis shows that solution accuracy masks distinct capability profiles, primitives unlock substantial latent execution capacity, and Discovery is the dominant bottleneck. Building on these findings, we introduce Absorb, a primitive-privileged self-distillation framework that consistently improves mathematical reasoning across model scales and challenging benchmarks.
Generative AI for Autonomous Driving: Frontiers and Opportunities
Yuping Wang, Shuo Xing, Can Cui, Renjie Li, Hongyuan Hua, Kexin Tian, Zhaobin Mo, Xiangbo Gao, Marco Pavone, Yang Zhou, Jiachen Li, Zhengzhong Tu
ACM Computing Surveys (CSUR) 2026

This survey delivers a comprehensive and critical synthesis of the emerging role of GenAI across the autonomous driving stack. We begin by distilling the principles and trade-offs of modern generative modeling, encompassing VAEs, GANs, Diffusion Models, and Large Language Models (LLMs)
Generative AI for Autonomous Driving: Frontiers and Opportunities
Yuping Wang, Shuo Xing, Can Cui, Renjie Li, Hongyuan Hua, Kexin Tian, Zhaobin Mo, Xiangbo Gao, Marco Pavone, Yang Zhou, Jiachen Li, Zhengzhong Tu
ACM Computing Surveys (CSUR) 2026
This survey delivers a comprehensive and critical synthesis of the emerging role of GenAI across the autonomous driving stack. We begin by distilling the principles and trade-offs of modern generative modeling, encompassing VAEs, GANs, Diffusion Models, and Large Language Models (LLMs)
TimePre: Bridging Accuracy, Efficiency, and Stability in Probabilistic Time-Series Forecasting
Lingyu Jiang*, Lingyu Xu*, Peiran Li, Dengzhe Hou, Qianwen Ge, Dingyi Zhuang, Shuo Xing, Wenjing Chen, Xiangbo Gao, Ting-Hsuan Chen, Xueying Zhan, Xin Zhang, Ziming Zhang, Zhengzhong Tu, Michael Zielewski, Kazunori Yamada, Fangzhou Lin (* equal contribution)
Transactions on Machine Learning Research (TMLR) 2026
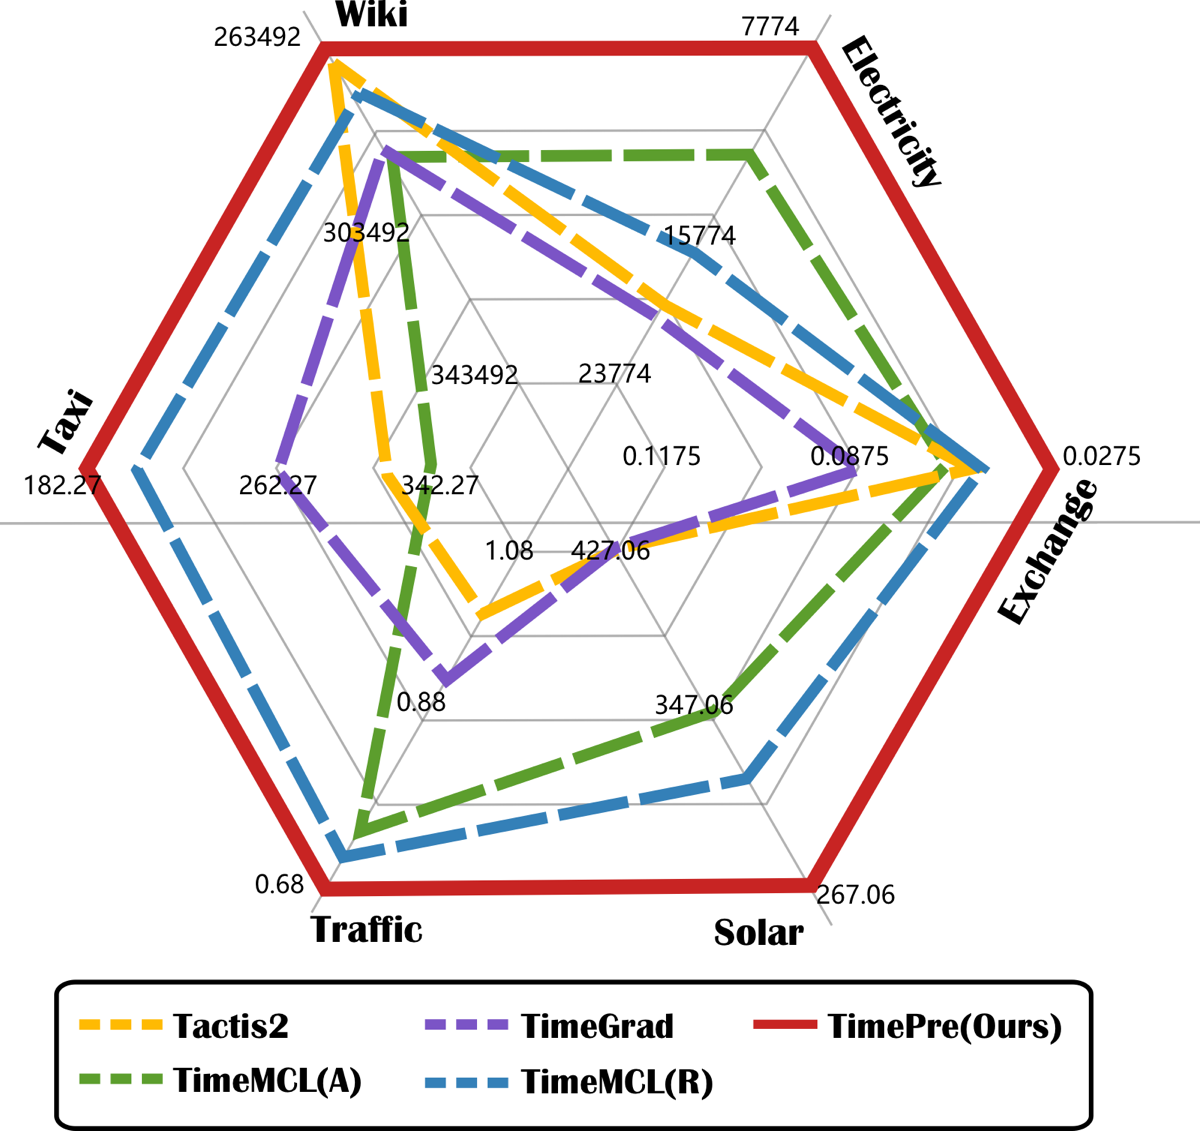
We propose TimePre, a simple framework that unifies the efficiency of MLP-based models with the distributional flexibility of Multiple Choice Learning (MCL) for probabilistic time-series forecasting. Its core, Stabilized Instance Normalization (SIN), corrects channel-wise statistical shifts to resolve catastrophic hypothesis collapse. TimePre achieves state-of-the-art accuracy on six benchmarks with inference speeds orders of magnitude faster than sampling-based models.
TimePre: Bridging Accuracy, Efficiency, and Stability in Probabilistic Time-Series Forecasting
Lingyu Jiang*, Lingyu Xu*, Peiran Li, Dengzhe Hou, Qianwen Ge, Dingyi Zhuang, Shuo Xing, Wenjing Chen, Xiangbo Gao, Ting-Hsuan Chen, Xueying Zhan, Xin Zhang, Ziming Zhang, Zhengzhong Tu, Michael Zielewski, Kazunori Yamada, Fangzhou Lin (* equal contribution)
Transactions on Machine Learning Research (TMLR) 2026
We propose TimePre, a simple framework that unifies the efficiency of MLP-based models with the distributional flexibility of Multiple Choice Learning (MCL) for probabilistic time-series forecasting. Its core, Stabilized Instance Normalization (SIN), corrects channel-wise statistical shifts to resolve catastrophic hypothesis collapse. TimePre achieves state-of-the-art accuracy on six benchmarks with inference speeds orders of magnitude faster than sampling-based models.
CinematicVQA: Benchmarking Film-Grammar Reasoning in Large Vision-Language Models
Shuo Xing, Pooja Verlani, Balu Adsumilli, Zhengzhong Tu
IEEE International Workshop on Multimedia Signal Processing (MMSP) 2026
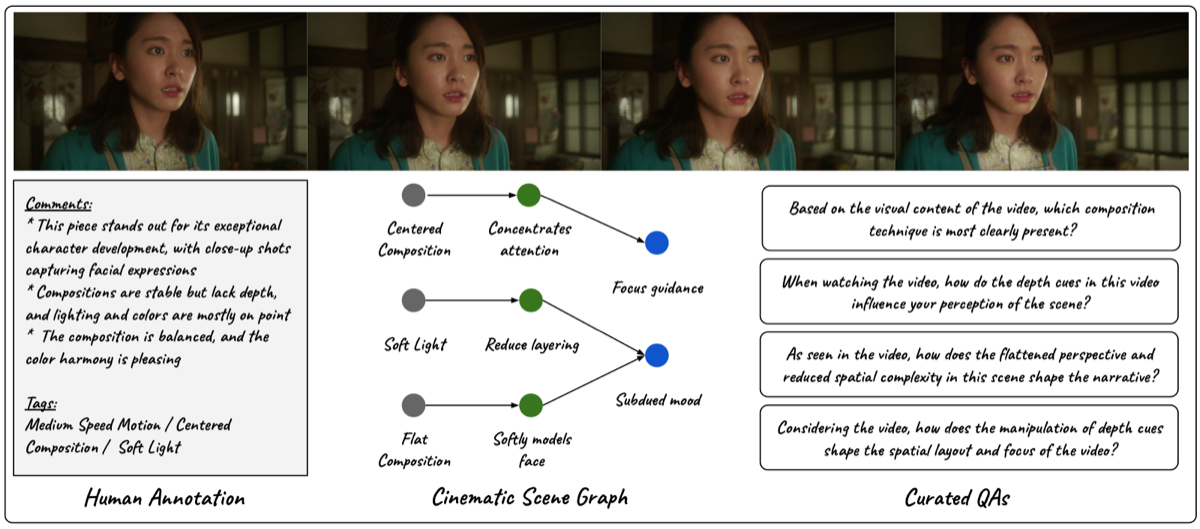
We introduce CinematicVQA, the first-of-its-kind benchmark for cinematic video understanding that goes beyond technique recognition to evaluate film-grammar reasoning, utilizing our Cinematic Scene Graph (CSG), a structured representation that links filming techniques to their perceptual effects and narrative functions. Through comprehensive evaluation of state-of-the-art LVLMs, we reveal a striking semantic gap: models consistently perform higher on describing visual presentations than on identifying the underlying techniques, and Chain-of-Thought prompting fails to provide consistent gains. Fine-tuning on CinematicVQA-train yields consistent improvements, particularly for narrative function and multi-hop reasoning.
CinematicVQA: Benchmarking Film-Grammar Reasoning in Large Vision-Language Models
Shuo Xing, Pooja Verlani, Balu Adsumilli, Zhengzhong Tu
IEEE International Workshop on Multimedia Signal Processing (MMSP) 2026
We introduce CinematicVQA, the first-of-its-kind benchmark for cinematic video understanding that goes beyond technique recognition to evaluate film-grammar reasoning, utilizing our Cinematic Scene Graph (CSG), a structured representation that links filming techniques to their perceptual effects and narrative functions. Through comprehensive evaluation of state-of-the-art LVLMs, we reveal a striking semantic gap: models consistently perform higher on describing visual presentations than on identifying the underlying techniques, and Chain-of-Thought prompting fails to provide consistent gains. Fine-tuning on CinematicVQA-train yields consistent improvements, particularly for narrative function and multi-hop reasoning.
LLMs Can Get "Brain Rot": A Pilot Study on Twitter/X
Shuo Xing*, Junyuan Hong*#, Yifan Wang, Runjin Chen, Zhenyu Zhang, Ananth Grama, Zhengzhong Tu, Zhangyang Wang# (* equal contribution, # corresponding author)
Conference on Language Modeling (COLM) 2026

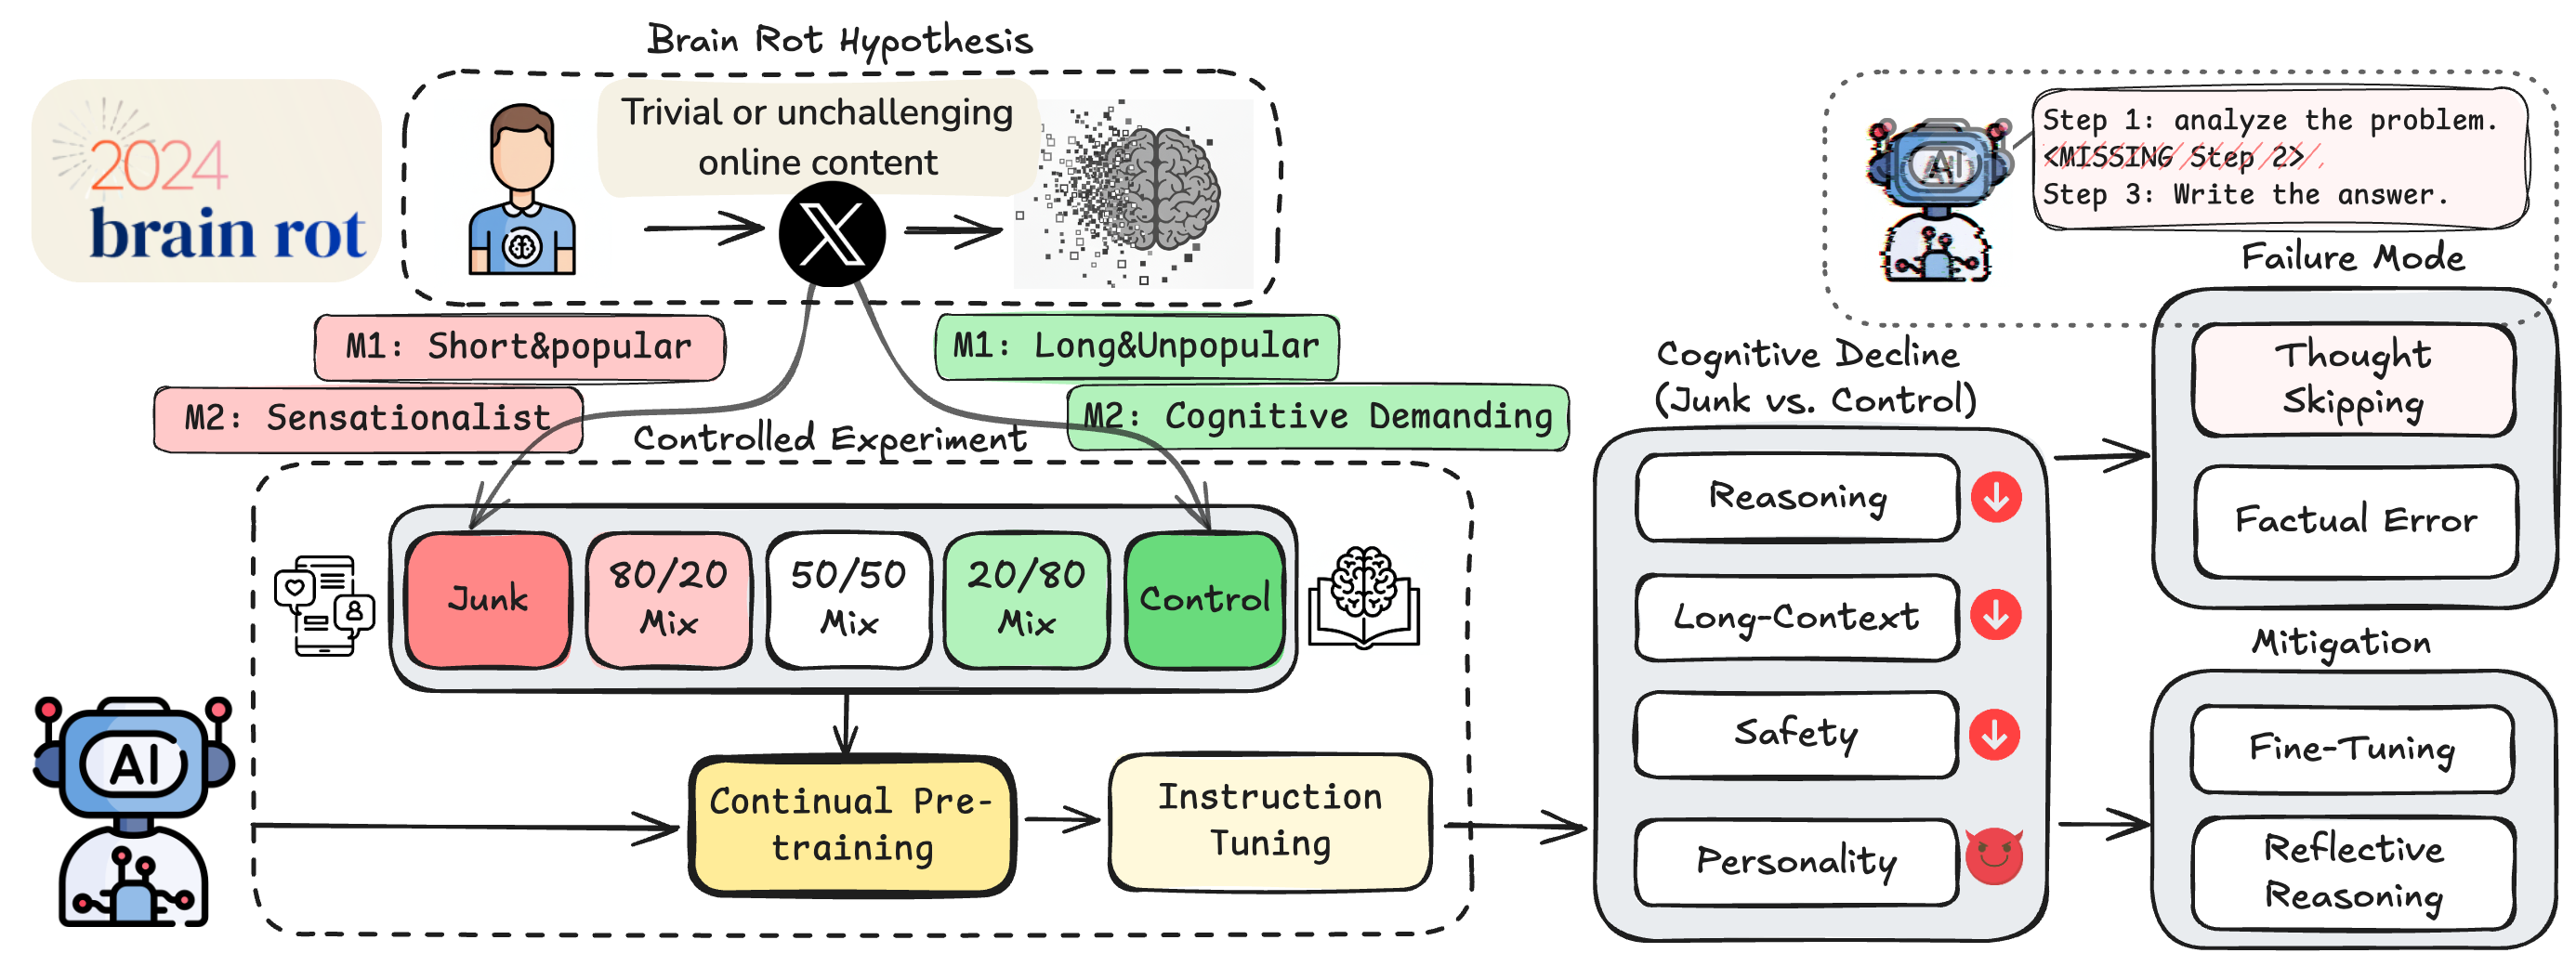
We propose and test the LLM Brain Rot Hypothesis: continual exposure to junk web text causes lasting cognitive decline in large language models. Using real Twitter/X corpora, we build matched junk and control datasets along two orthogonal dimensions—M1 (engagement) and M2 (semantic quality)—and continually pre-train four LLMs. Junk-fed models show clear deterioration (Hedges’ g > 0.3) in reasoning, long-context understanding, safety, and personality alignment. Performance decays with increasing junk ratio (e.g., ARC-CoT 74.9 → 57.2, RULER-CWE 84.4 → 52.3). Forensics reveal: (1) Thought-skipping as the core lesion; (2) Partial, irreversible recovery despite further tuning; and (3) Popularity, not text length, as the strongest predictor of “brain rot.”
LLMs Can Get "Brain Rot": A Pilot Study on Twitter/X
Shuo Xing*, Junyuan Hong*#, Yifan Wang, Runjin Chen, Zhenyu Zhang, Ananth Grama, Zhengzhong Tu, Zhangyang Wang# (* equal contribution, # corresponding author)
Conference on Language Modeling (COLM) 2026
We propose and test the LLM Brain Rot Hypothesis: continual exposure to junk web text causes lasting cognitive decline in large language models. Using real Twitter/X corpora, we build matched junk and control datasets along two orthogonal dimensions—M1 (engagement) and M2 (semantic quality)—and continually pre-train four LLMs. Junk-fed models show clear deterioration (Hedges’ g > 0.3) in reasoning, long-context understanding, safety, and personality alignment. Performance decays with increasing junk ratio (e.g., ARC-CoT 74.9 → 57.2, RULER-CWE 84.4 → 52.3). Forensics reveal: (1) Thought-skipping as the core lesion; (2) Partial, irreversible recovery despite further tuning; and (3) Popularity, not text length, as the strongest predictor of “brain rot.”
A Compact Kolmogorov–Arnold Network Mixer for Long-Term Time Series Forecasting
Lingyu Jiang, Dengzhe Hou, Yuping Wang, Yao Su, Shuo Xing, Wenjing Chen, Xin Zhang, Zhengzhong Tu, Ziming Zhang, Fangzhou Lin, Michael Zielewski, Kazunori Yamada
Scientific Reports 2026
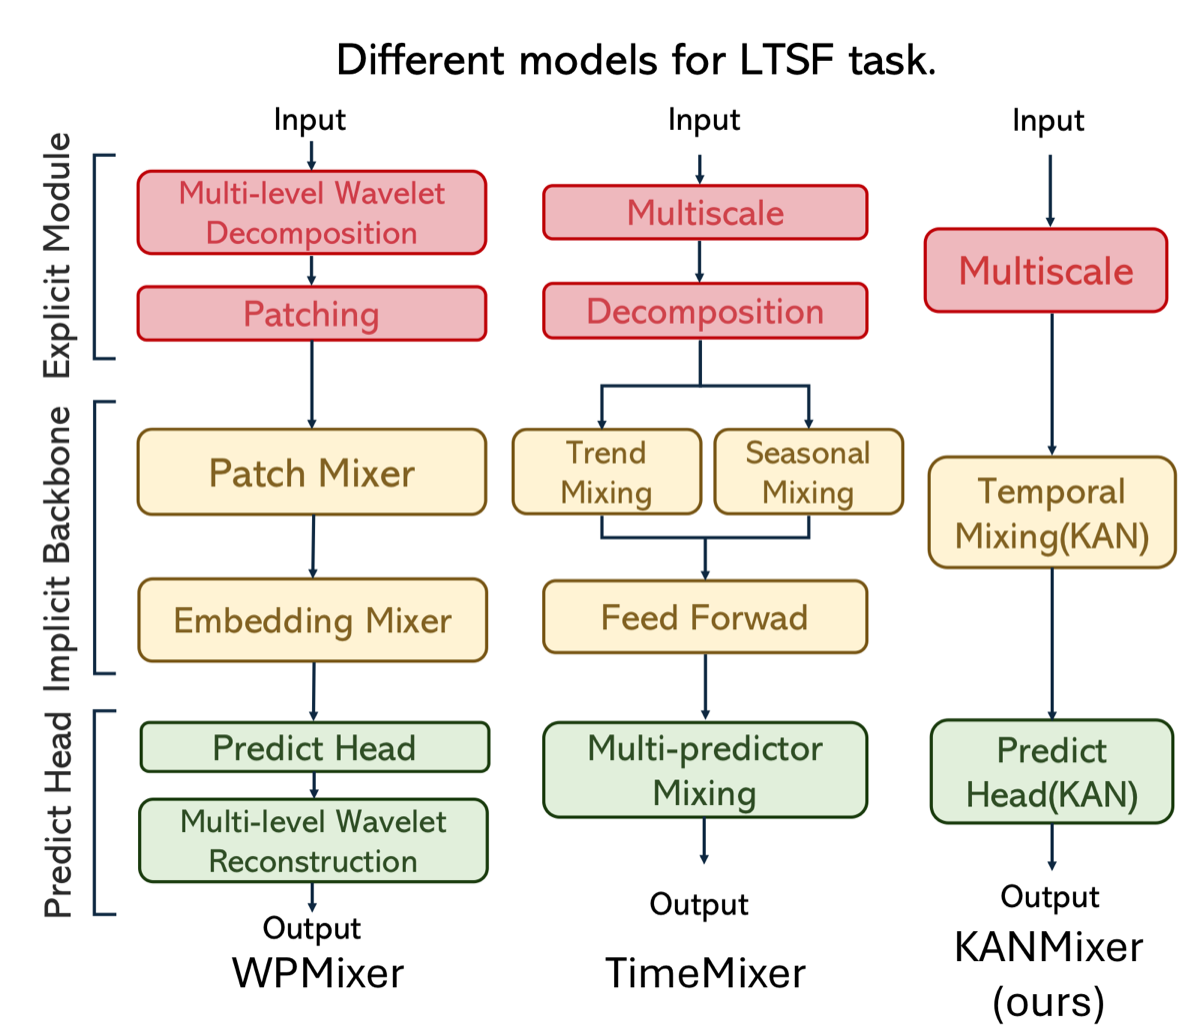
We investigate whether Kolmogorov–Arnold Networks (KANs) can serve as effective modeling components for long-term time series forecasting, and propose KANMixer, a compact KAN-centered architecture consisting of a multi-scale pooling frontend, a KAN-based temporal mixing backbone, and prediction heads. Across 28 benchmark-horizon settings against nine baselines, KANMixer achieves the best MSE in 16 settings, and ablations reveal that design choices that benefit MLPs, such as decomposition priors, can degrade KANs.
A Compact Kolmogorov–Arnold Network Mixer for Long-Term Time Series Forecasting
Lingyu Jiang, Dengzhe Hou, Yuping Wang, Yao Su, Shuo Xing, Wenjing Chen, Xin Zhang, Zhengzhong Tu, Ziming Zhang, Fangzhou Lin, Michael Zielewski, Kazunori Yamada
Scientific Reports 2026
We investigate whether Kolmogorov–Arnold Networks (KANs) can serve as effective modeling components for long-term time series forecasting, and propose KANMixer, a compact KAN-centered architecture consisting of a multi-scale pooling frontend, a KAN-based temporal mixing backbone, and prediction heads. Across 28 benchmark-horizon settings against nine baselines, KANMixer achieves the best MSE in 16 settings, and ablations reveal that design choices that benefit MLPs, such as decomposition priors, can degrade KANs.
VGBE 2026 Challenge on Image-to-Video Consistent Generation: Methods and Results
Mingyang Wu, Siyuan Yang, Shuo Xing, Ashirbad Mishra, Soumik Dey, Xiangbo Gao, Jinyu Zhao, Jiongze Yu, Fangzhou Lin, Zhengzhong Tu, ...
IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) 2026
This paper presents an overview of the VGBE 2026 Challenge on Image-to-Video Consistent Generation, which addresses temporal distortion and appearance drift in generative video. Given a single reference image and a text prompt, participants generated video sequences that adhere to text instructions while maintaining visual identity, geometric coherence, and high perceptual quality, evaluated with a composite protocol of objective metrics and subjective human assessments.
VGBE 2026 Challenge on Image-to-Video Consistent Generation: Methods and Results
Mingyang Wu, Siyuan Yang, Shuo Xing, Ashirbad Mishra, Soumik Dey, Xiangbo Gao, Jinyu Zhao, Jiongze Yu, Fangzhou Lin, Zhengzhong Tu, ...
IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) 2026
This paper presents an overview of the VGBE 2026 Challenge on Image-to-Video Consistent Generation, which addresses temporal distortion and appearance drift in generative video. Given a single reference image and a text prompt, participants generated video sequences that adhere to text instructions while maintaining visual identity, geometric coherence, and high perceptual quality, evaluated with a composite protocol of objective metrics and subjective human assessments.
CV-Arena: An Open Benchmark for Instructional Computer Vision Problem Solving with Human-AI Collaborative Preferences
Fangzhou Lin, Peiran Li, Lingyu Xu, Wenjing Chen, Qianwen Ge, Shuo Xing, Mingyang Wu, Xiangbo Gao, Siyuan Yang, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhen Dong, Ming-Hsuan Yang, Zhengzhong Tu
arXiv preprint 2026
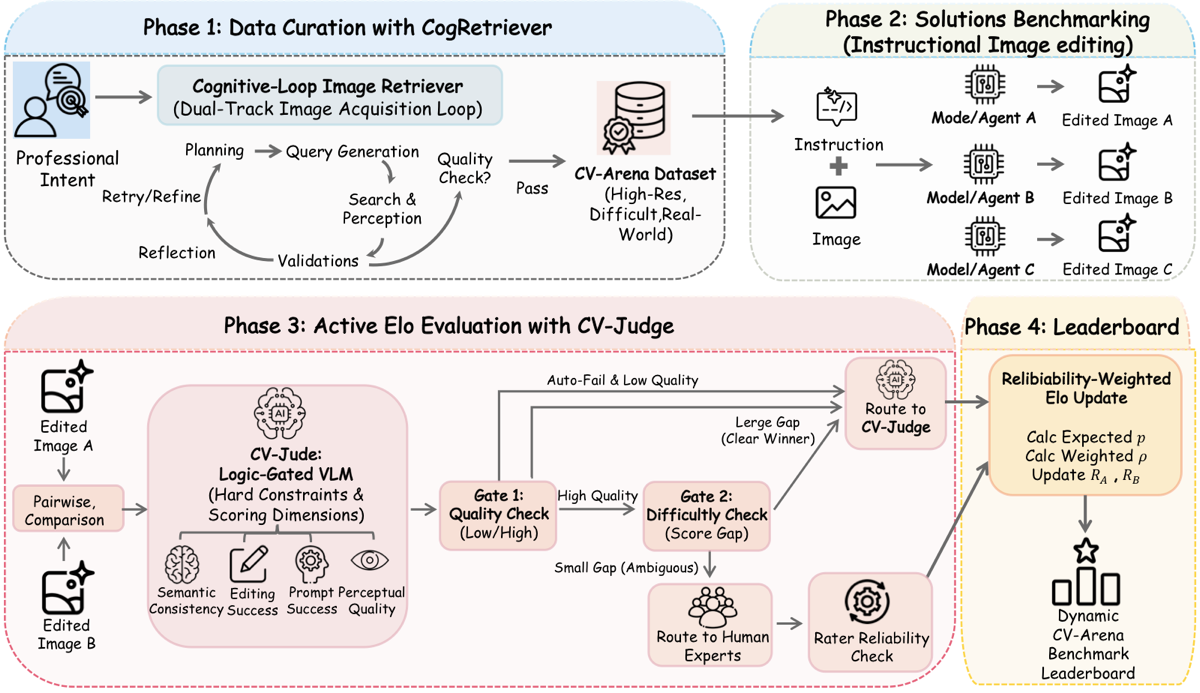
We introduce CV-Arena, an open benchmark for instructional computer vision problem solving, containing 12K high-resolution real-image instruction pairs spanning 16 instruction-based visual task types. To evaluate models at scale while preserving human fidelity, we propose Active Elo, a human-AI collaborative preference protocol that uses CV-Judge, a multi-dimensional VLM evaluator, to resolve clear comparisons and routes close, high-quality comparisons to expert raters. Our evaluation of 21 systems reveals persistent gaps in instruction adherence, physical reasoning, structural control, and fine-grained detail preservation.
CV-Arena: An Open Benchmark for Instructional Computer Vision Problem Solving with Human-AI Collaborative Preferences
Fangzhou Lin, Peiran Li, Lingyu Xu, Wenjing Chen, Qianwen Ge, Shuo Xing, Mingyang Wu, Xiangbo Gao, Siyuan Yang, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhen Dong, Ming-Hsuan Yang, Zhengzhong Tu
arXiv preprint 2026
We introduce CV-Arena, an open benchmark for instructional computer vision problem solving, containing 12K high-resolution real-image instruction pairs spanning 16 instruction-based visual task types. To evaluate models at scale while preserving human fidelity, we propose Active Elo, a human-AI collaborative preference protocol that uses CV-Judge, a multi-dimensional VLM evaluator, to resolve clear comparisons and routes close, high-quality comparisons to expert raters. Our evaluation of 21 systems reveals persistent gaps in instruction adherence, physical reasoning, structural control, and fine-grained detail preservation.
PathCal: State-Aware Reflection-Marker Calibration for Efficient Reasoning
Lingyu Jiang, Zirui Li, Shuo Xing, Peiran Li, Tsubasa Takahashi, Dengzhe Hou, Zhengzhong Tu, Kazunori Yamada, Fangzhou Lin
arXiv preprint 2026
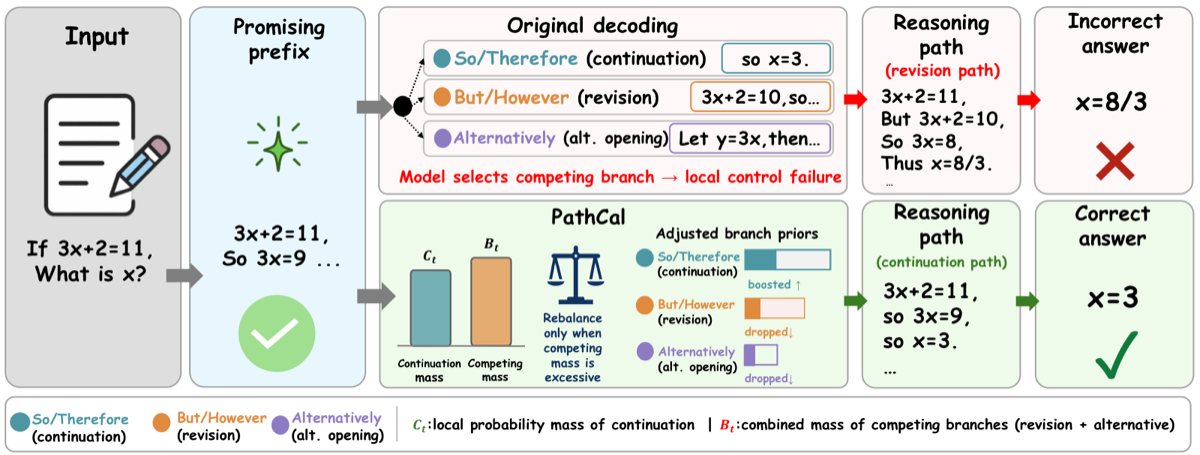
Through type-wise suppression and fixed-prefix intervention, we reveal that reflection markers in long chain-of-thought (e.g., "wait", "but", "alternatively") differ not only in their functional roles but also in when they exert the greatest influence. Motivated by these findings, we introduce PathCal, a training-free decoding controller that calibrates reasoning paths by distinguishing marker types and intervening only at locally uncertain states. Experiments across six reasoning benchmarks show that PathCal improves or preserves accuracy while reducing generation length, without external verifiers or additional sampling.
PathCal: State-Aware Reflection-Marker Calibration for Efficient Reasoning
Lingyu Jiang, Zirui Li, Shuo Xing, Peiran Li, Tsubasa Takahashi, Dengzhe Hou, Zhengzhong Tu, Kazunori Yamada, Fangzhou Lin
arXiv preprint 2026
Through type-wise suppression and fixed-prefix intervention, we reveal that reflection markers in long chain-of-thought (e.g., "wait", "but", "alternatively") differ not only in their functional roles but also in when they exert the greatest influence. Motivated by these findings, we introduce PathCal, a training-free decoding controller that calibrates reasoning paths by distinguishing marker types and intervening only at locally uncertain states. Experiments across six reasoning benchmarks show that PathCal improves or preserves accuracy while reducing generation length, without external verifiers or additional sampling.
CAPS: Cascaded Adaptive Pairwise Selection for Efficient Parallel Reasoning
Fangzhou Lin, Shuo Xing, Peiran Li, Siyuan Yang, Qianwen Ge, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
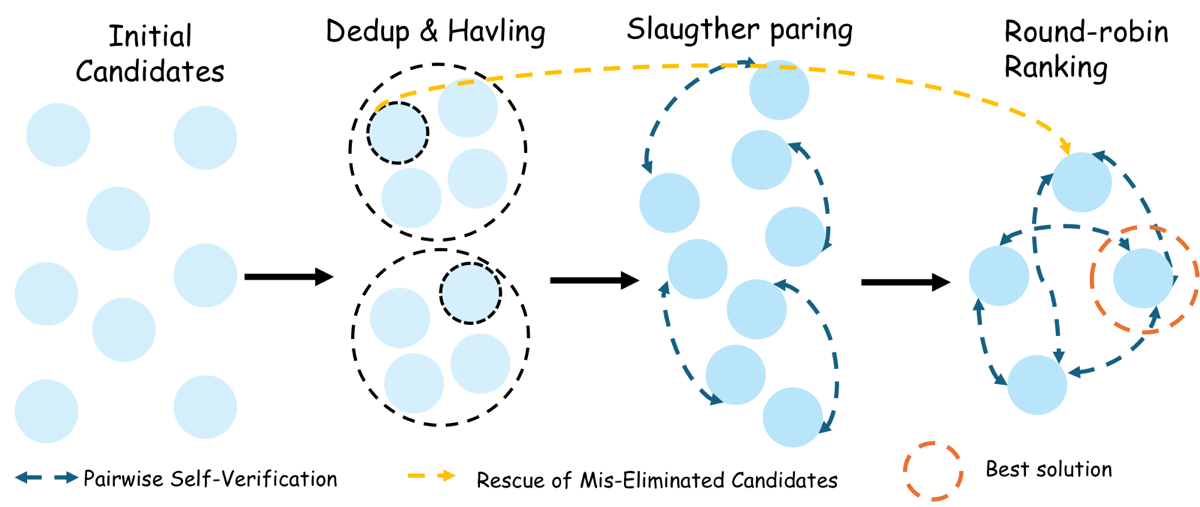
We introduce CAPS (Cascaded Adaptive Pairwise Selection), an inference-only framework for parallel reasoning that allocates verifier compute non-uniformly along two axes: an evidence axis that adapts how much of each candidate the judge sees, and a distribution axis that adapts how comparisons are spread across the pool. On four self-verifying models and five code and math benchmarks, CAPS outperforms the leading pairwise verifier on 14 of 20 suites while using 25.4% of its verifier-token budget on code.
CAPS: Cascaded Adaptive Pairwise Selection for Efficient Parallel Reasoning
Fangzhou Lin, Shuo Xing, Peiran Li, Siyuan Yang, Qianwen Ge, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
We introduce CAPS (Cascaded Adaptive Pairwise Selection), an inference-only framework for parallel reasoning that allocates verifier compute non-uniformly along two axes: an evidence axis that adapts how much of each candidate the judge sees, and a distribution axis that adapts how comparisons are spread across the pool. On four self-verifying models and five code and math benchmarks, CAPS outperforms the leading pairwise verifier on 14 of 20 suites while using 25.4% of its verifier-token budget on code.
Multi-Agent Reinforcement Learning with Submodular Reward
Wenjing Chen, Chengyuan Qian, Shuo Xing, Yi Zhou, Victoria G. Crawford
The 43rd International Conference on Machine Learning (ICML) 2026
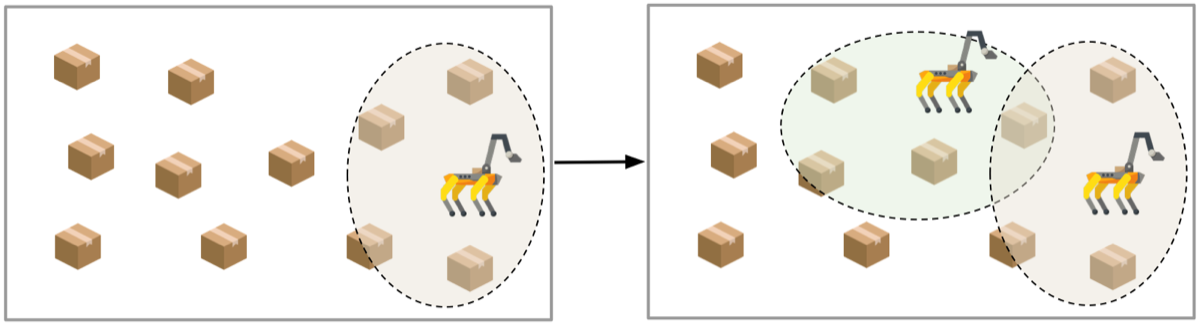
We study cooperative multi-agent reinforcement learning (MARL) where the joint reward exhibits submodularity, capturing diminishing marginal returns when adding agents to a team, and provide the first formal framework for this setting. For known dynamics, our greedy policy optimization achieves a $1/2$-approximation with polynomial complexity in the number of agents; for unknown dynamics, we propose a UCB-based learning algorithm achieving a $1/2$-regret of $O(H^2KS\sqrt{AT})$.
Multi-Agent Reinforcement Learning with Submodular Reward
Wenjing Chen, Chengyuan Qian, Shuo Xing, Yi Zhou, Victoria G. Crawford
The 43rd International Conference on Machine Learning (ICML) 2026
We study cooperative multi-agent reinforcement learning (MARL) where the joint reward exhibits submodularity, capturing diminishing marginal returns when adding agents to a team, and provide the first formal framework for this setting. For known dynamics, our greedy policy optimization achieves a $1/2$-approximation with polynomial complexity in the number of agents; for unknown dynamics, we propose a UCB-based learning algorithm achieving a $1/2$-regret of $O(H^2KS\sqrt{AT})$.
AdaptFuse: Training-Free Sequential Preference Learning via Externalized Bayesian Inference
Fangzhou Lin, Peiran Li, Shuo Xing, Siyuan Yang, Qianwen Ge, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
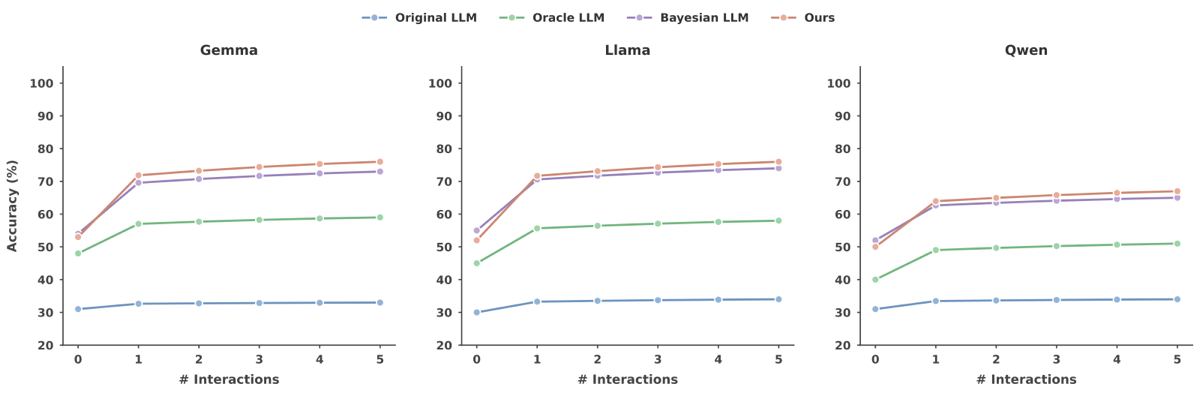
We propose AdaptFuse, a training-free framework that externalizes probabilistic computation from the LLM: a symbolic module maintains a Bayesian posterior over a discrete hypothesis set, while a frozen LLM contributes semantic reasoning, and the two signals are combined through entropy-adaptive fusion. Across flight recommendation, hotel recommendation, and web shopping, AdaptFuse consistently outperforms both prompting baselines and fine-tuned Bayesian Teaching models, without storing or training on sensitive user data.
AdaptFuse: Training-Free Sequential Preference Learning via Externalized Bayesian Inference
Fangzhou Lin, Peiran Li, Shuo Xing, Siyuan Yang, Qianwen Ge, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
We propose AdaptFuse, a training-free framework that externalizes probabilistic computation from the LLM: a symbolic module maintains a Bayesian posterior over a discrete hypothesis set, while a frozen LLM contributes semantic reasoning, and the two signals are combined through entropy-adaptive fusion. Across flight recommendation, hotel recommendation, and web shopping, AdaptFuse consistently outperforms both prompting baselines and fine-tuned Bayesian Teaching models, without storing or training on sensitive user data.
Does RLVR Extend Reasoning Boundaries? Investigating Capability Expansion in Vision-Language Models
Minghe Shen, Zhuo Zhi, Chonghan Liu, Shuo Xing, Zhengzhong Tu, Che Liu
Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (ACL) 2026
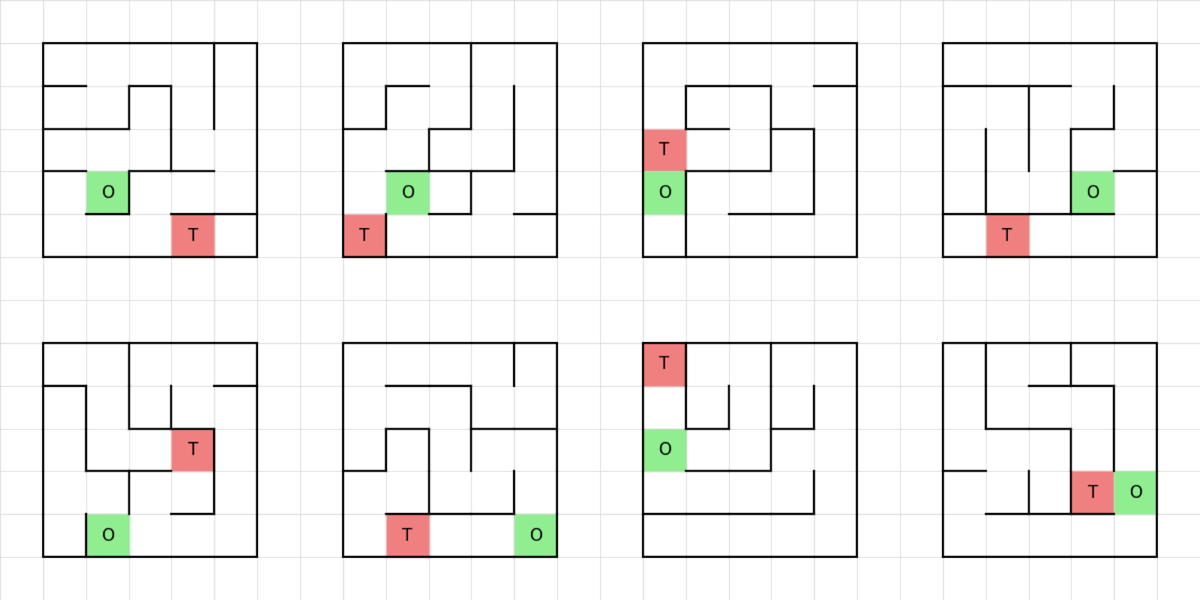
We introduce Ariadne, a controlled framework based on synthetic maze navigation where reasoning difficulty is precisely regulated, to examine the impact of Reinforcement Learning with Verifiable Rewards (RLVR) on the capability boundaries of Vision-Language Models. We show that RLVR extends the spatial reasoning boundary, succeeding on problems where the base model consistently attains 0% accuracy despite increasing pass@k budgets, and that the gains transfer zero-shot to real-world navigation benchmarks (MapBench and ReasonMap).
Does RLVR Extend Reasoning Boundaries? Investigating Capability Expansion in Vision-Language Models
Minghe Shen, Zhuo Zhi, Chonghan Liu, Shuo Xing, Zhengzhong Tu, Che Liu
Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (ACL) 2026
We introduce Ariadne, a controlled framework based on synthetic maze navigation where reasoning difficulty is precisely regulated, to examine the impact of Reinforcement Learning with Verifiable Rewards (RLVR) on the capability boundaries of Vision-Language Models. We show that RLVR extends the spatial reasoning boundary, succeeding on problems where the base model consistently attains 0% accuracy despite increasing pass@k budgets, and that the gains transfer zero-shot to real-world navigation benchmarks (MapBench and ReasonMap).
Let the Abyss Stare Back: Adaptive Falsification for Autonomous Scientific Discovery
Peiran Li, Fangzhou Lin, Shuo Xing, Jiashuo Sun, Dylan Zhang, Siyuan Yang, Chaoqun Ni, Zhengzhong Tu
arXiv preprint 2026
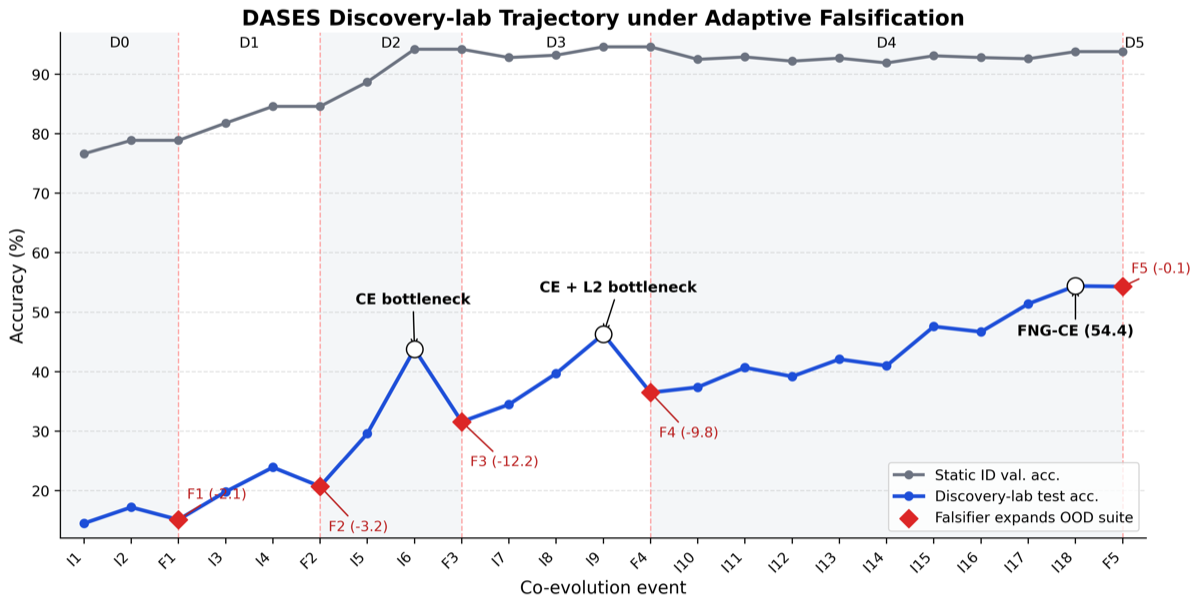
Once the evaluator is frozen, a sufficiently strong search process can learn to win the exam without learning the mechanism the task was meant to reveal. We introduce DASES, a falsification-driven framework in which an Innovator, an Abyss Falsifier, and a Mechanistic Causal Extractor co-evolve executable scientific artifacts and admissible counterexample environments. In a controlled loss-discovery problem, DASES discovers FNG-CE, a loss that transfers beyond the discovery environment and consistently outperforms CE and CE+L2 across standard benchmarks, including ImageNet.
Let the Abyss Stare Back: Adaptive Falsification for Autonomous Scientific Discovery
Peiran Li, Fangzhou Lin, Shuo Xing, Jiashuo Sun, Dylan Zhang, Siyuan Yang, Chaoqun Ni, Zhengzhong Tu
arXiv preprint 2026
Once the evaluator is frozen, a sufficiently strong search process can learn to win the exam without learning the mechanism the task was meant to reveal. We introduce DASES, a falsification-driven framework in which an Innovator, an Abyss Falsifier, and a Mechanistic Causal Extractor co-evolve executable scientific artifacts and admissible counterexample environments. In a controlled loss-discovery problem, DASES discovers FNG-CE, a loss that transfers beyond the discovery environment and consistently outperforms CE and CE+L2 across standard benchmarks, including ImageNet.
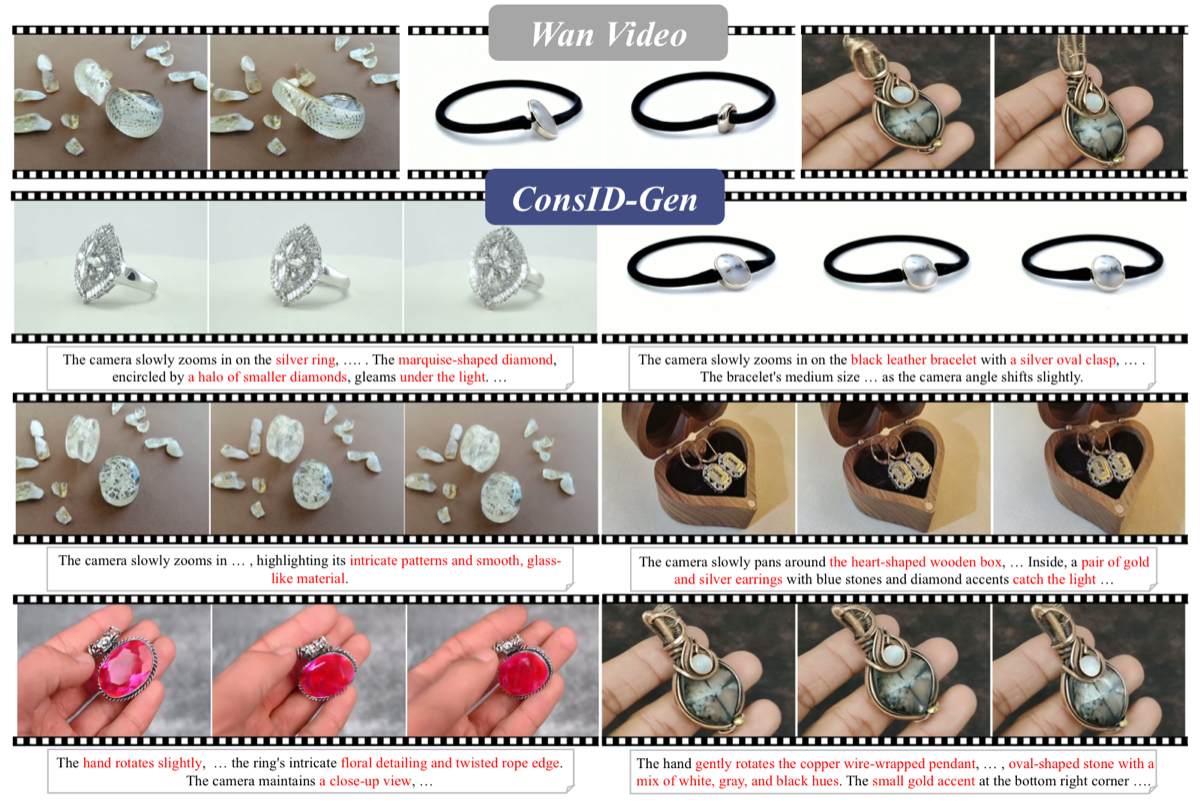
ConsID-Gen: View-Consistent and Identity-Preserving Image-to-Video Generation
Mingyang Wu, Ashirbad Mishra, Soumik Dey, Shuo Xing, Naveen Ravipati, Hansi Wu, Binbin Li, Zhengzhong Tu
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
We address identity preservation under changing viewpoints in image-to-video generation from both data and model perspectives. We curate ConsIDVid, a large-scale object-centric dataset with the ConsIDVid-Bench evaluation framework for multi-view consistency, and propose ConsID-Gen, a view-assisted I2V framework that augments the first frame with unposed auxiliary views and fuses semantic and structural cues via a dual-stream visual-geometric encoder. ConsID-Gen surpasses leading video generation models like Wan2.1 and HunyuanVideo, delivering superior identity fidelity and temporal coherence.
ConsID-Gen: View-Consistent and Identity-Preserving Image-to-Video Generation
Mingyang Wu, Ashirbad Mishra, Soumik Dey, Shuo Xing, Naveen Ravipati, Hansi Wu, Binbin Li, Zhengzhong Tu
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
We address identity preservation under changing viewpoints in image-to-video generation from both data and model perspectives. We curate ConsIDVid, a large-scale object-centric dataset with the ConsIDVid-Bench evaluation framework for multi-view consistency, and propose ConsID-Gen, a view-assisted I2V framework that augments the first frame with unposed auxiliary views and fuses semantic and structural cues via a dual-stream visual-geometric encoder. ConsID-Gen surpasses leading video generation models like Wan2.1 and HunyuanVideo, delivering superior identity fidelity and temporal coherence.
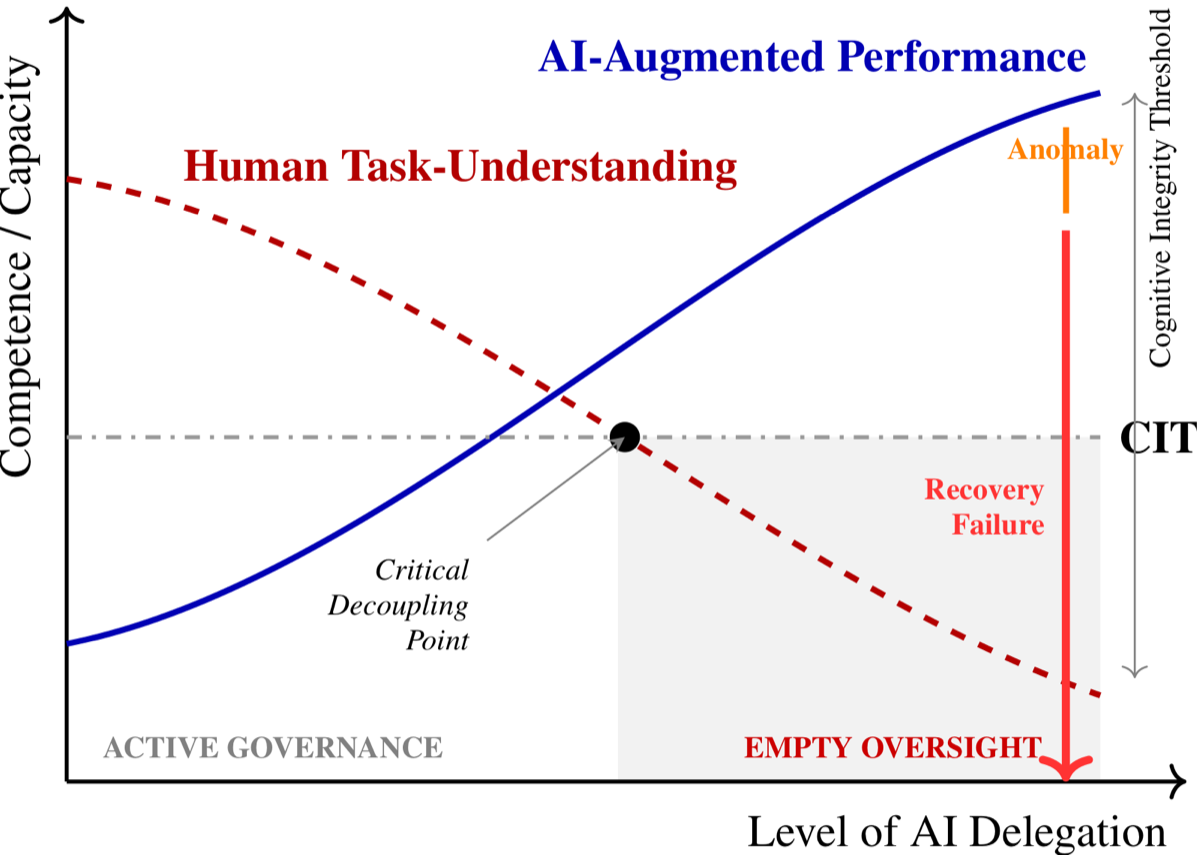
Position: Human-Centric AI Requires a Minimum Viable Level of Human Understanding
Fangzhou Lin, Qianwen Ge, Lingyu Xu, Peiran Li, Xiangbo Gao, Shuo Xing, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
AI systems increasingly produce fluent, correct, end-to-end outcomes, which over time erodes users' ability to explain, verify, or intervene; we define this divergence as the Capability-Comprehension Gap. We define the Cognitive Integrity Threshold (CIT) as the minimum comprehension required to preserve oversight, autonomy, and accountable participation under AI assistance, and operationalize it through verification capacity, comprehension-preserving interaction, and institutional scaffolds for governance.
Position: Human-Centric AI Requires a Minimum Viable Level of Human Understanding
Fangzhou Lin, Qianwen Ge, Lingyu Xu, Peiran Li, Xiangbo Gao, Shuo Xing, Kazunori Yamada, Ziming Zhang, Haichong Zhang, Zhengzhong Tu
arXiv preprint 2026
AI systems increasingly produce fluent, correct, end-to-end outcomes, which over time erodes users' ability to explain, verify, or intervene; we define this divergence as the Capability-Comprehension Gap. We define the Cognitive Integrity Threshold (CIT) as the minimum comprehension required to preserve oversight, autonomy, and accountable participation under AI assistance, and operationalize it through verification capacity, comprehension-preserving interaction, and institutional scaffolds for governance.
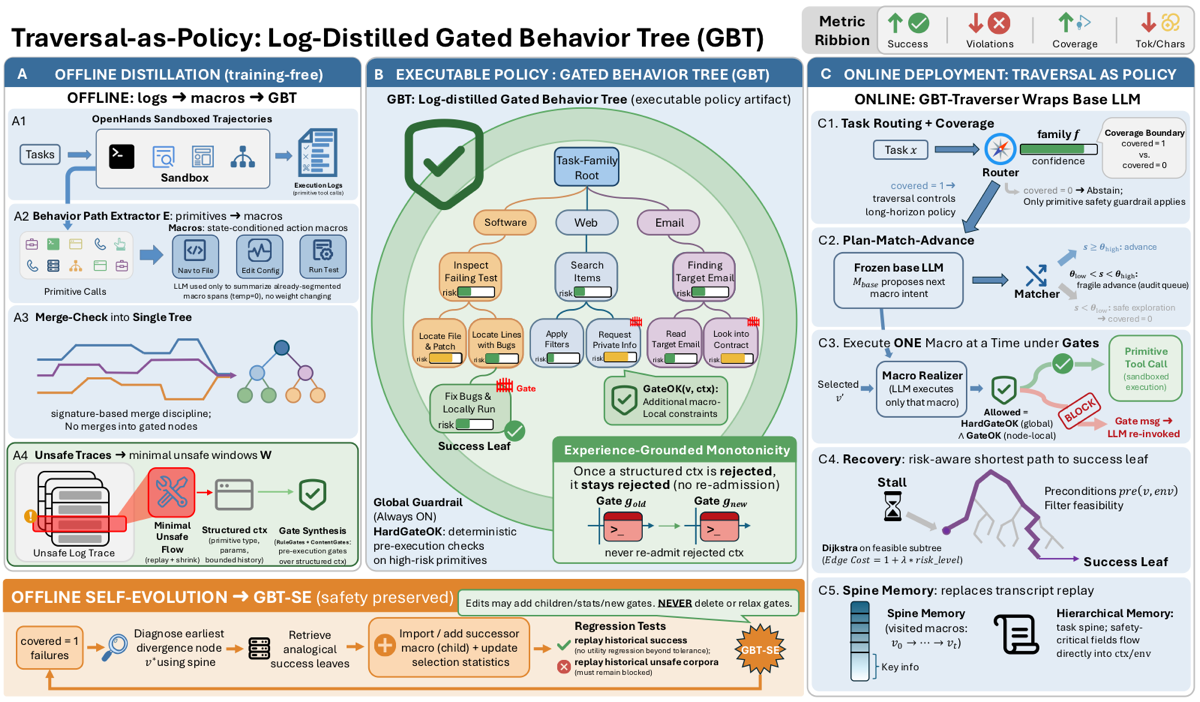
Traversal-as-Policy: Log-Distilled Gated Behavior Trees as Externalized, Verifiable Policies for Safe, Robust, and Efficient Agents
Peiran Li, Jiashuo Sun, Fangzhou Lin, Shuo Xing, Tianfu Fu, Suofei Feng, Chaoqun Ni, Zhengzhong Tu
arXiv preprint 2026
We propose Traversal-as-Policy: distill sandboxed agent execution logs into a single executable Gated Behavior Tree (GBT) and treat tree traversal, rather than unconstrained generation, as the control policy, with safety gates mined from unsafe traces and risk-aware recovery when the agent stalls. Across 15+ software, web, reasoning, and safety benchmarks, GBT improves success while driving violations toward zero and reducing cost; on SWE-bench Verified, it raises success from 34.6% to 73.6% and reduces violations from 2.8% to 0.2%.
Traversal-as-Policy: Log-Distilled Gated Behavior Trees as Externalized, Verifiable Policies for Safe, Robust, and Efficient Agents
Peiran Li, Jiashuo Sun, Fangzhou Lin, Shuo Xing, Tianfu Fu, Suofei Feng, Chaoqun Ni, Zhengzhong Tu
arXiv preprint 2026
We propose Traversal-as-Policy: distill sandboxed agent execution logs into a single executable Gated Behavior Tree (GBT) and treat tree traversal, rather than unconstrained generation, as the control policy, with safety gates mined from unsafe traces and risk-aware recovery when the agent stalls. Across 15+ software, web, reasoning, and safety benchmarks, GBT improves success while driving violations toward zero and reducing cost; on SWE-bench Verified, it raises success from 34.6% to 73.6% and reduces violations from 2.8% to 0.2%.
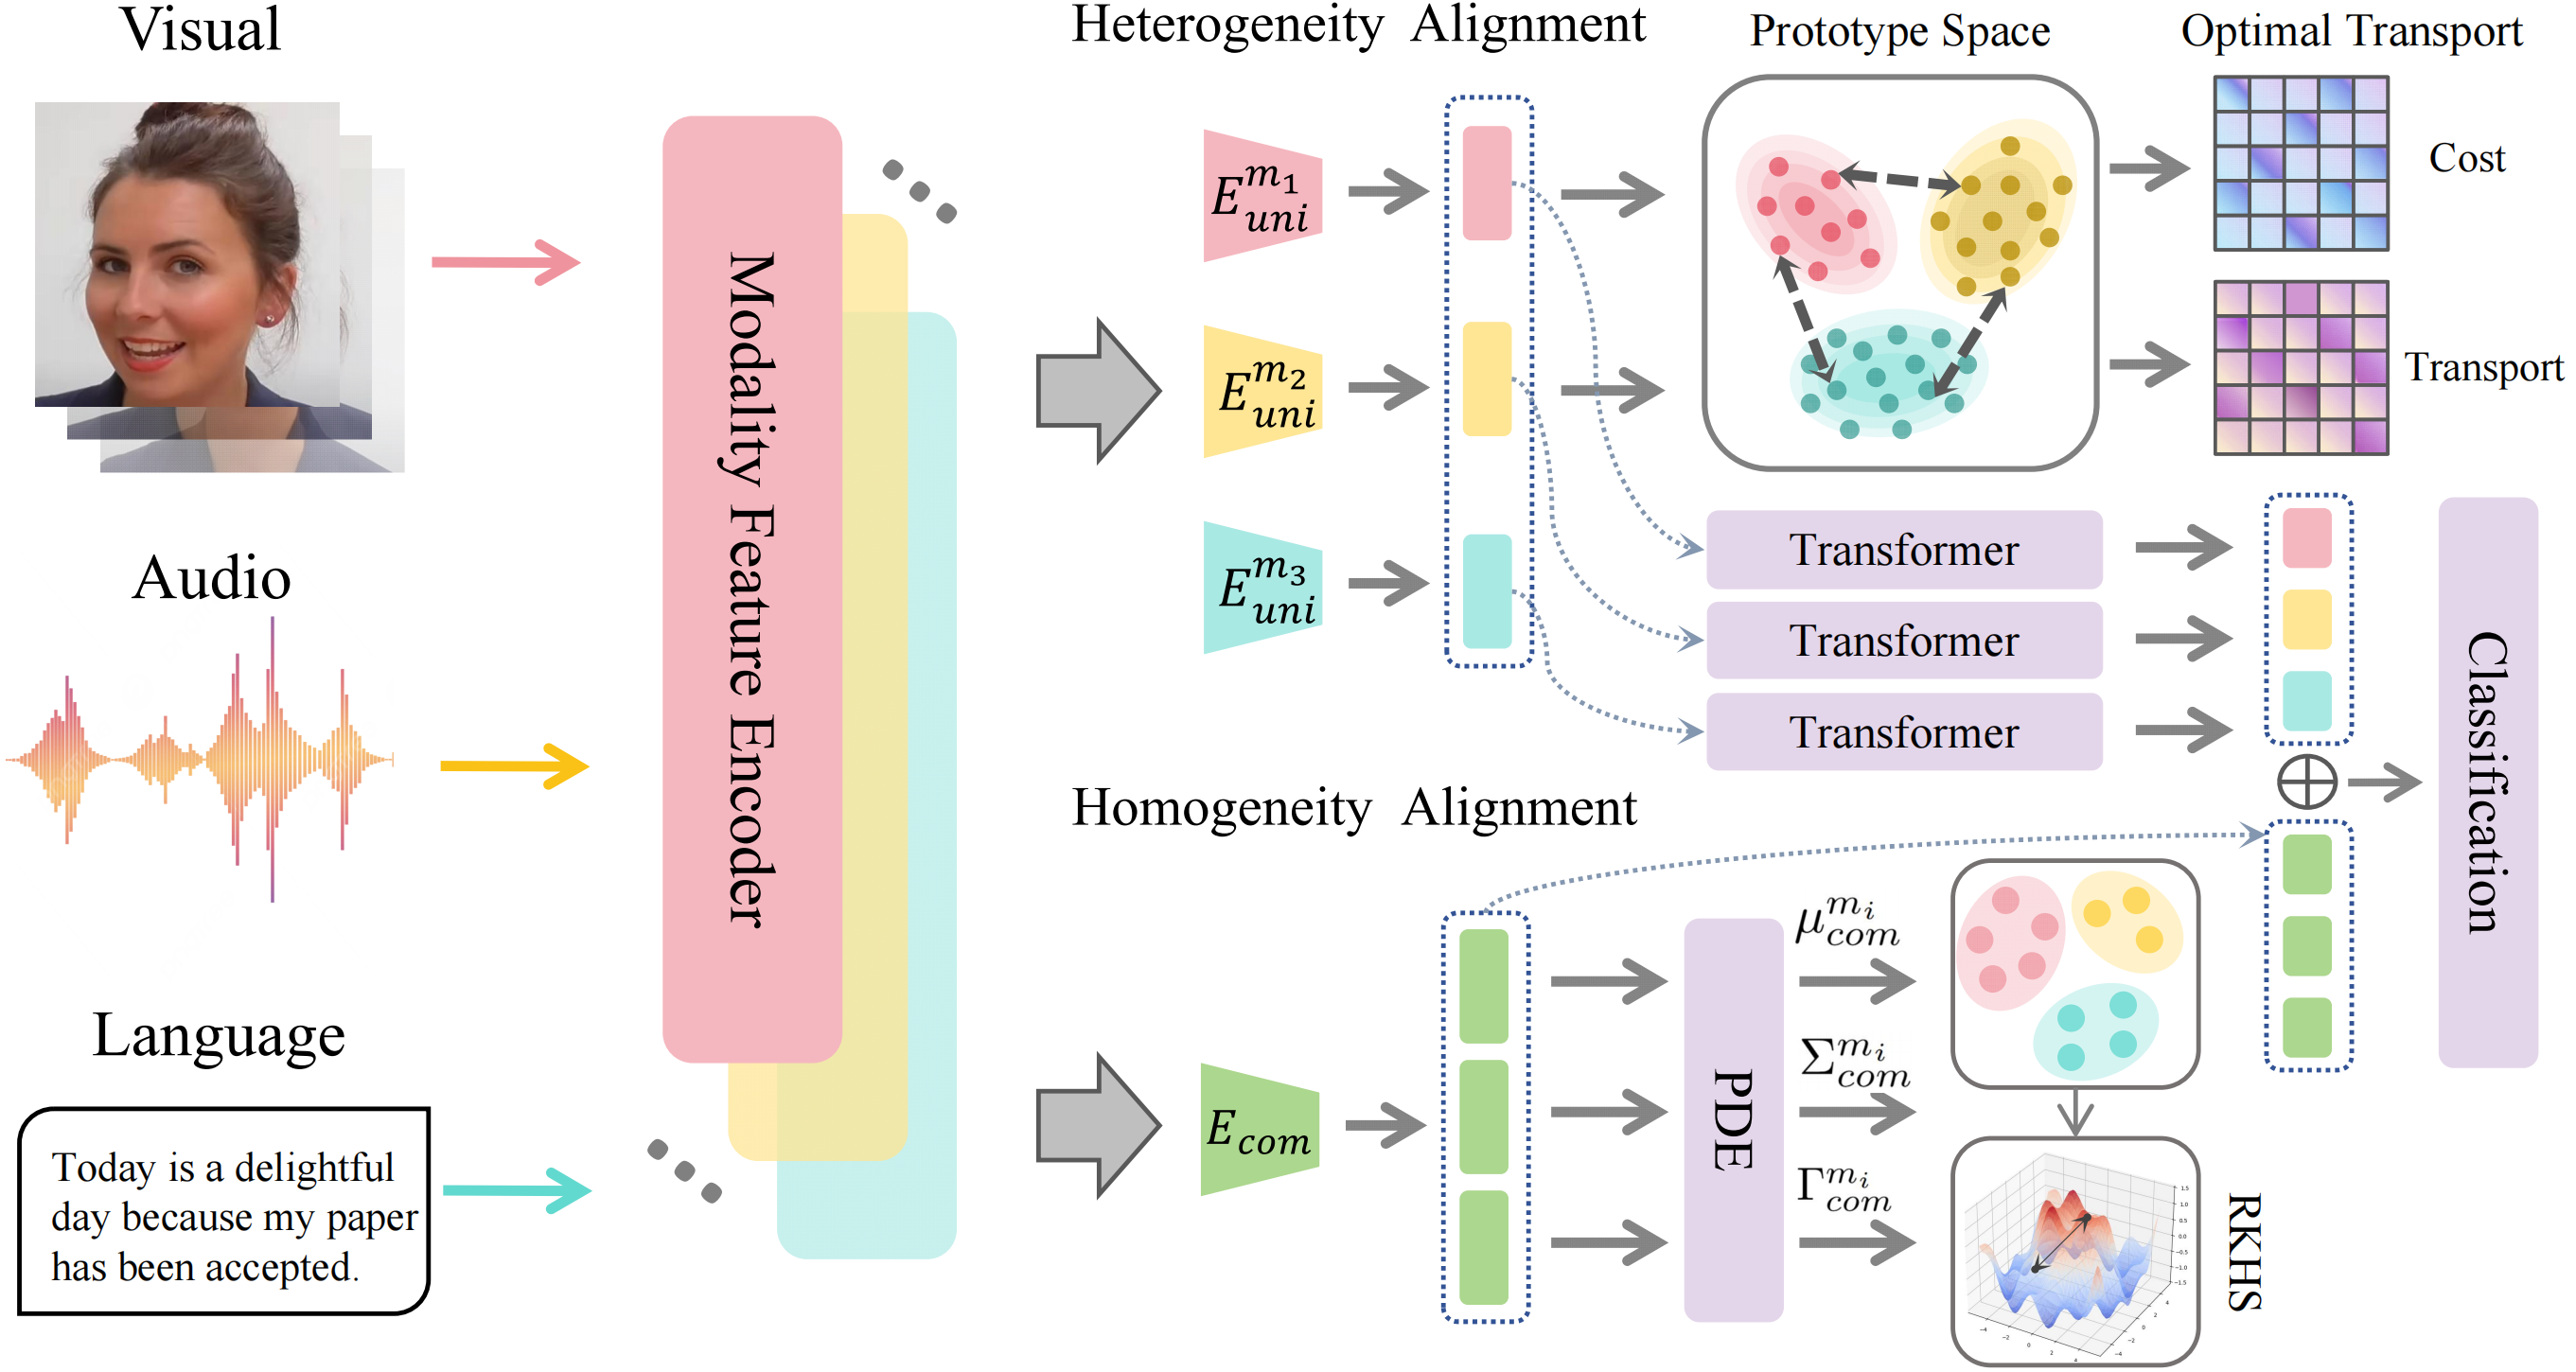
DecAlign: Hierarchical Cross-Modal Alignment for Decoupled Multimodal Representation Learning
Chengxuan Qian, Shuo Xing, Shawn Li, Yue Zhao, Zhengzhong Tu
The Fourteenth International Conference on Learning Representations (ICLR) 2026

We introduce DecAlign, a novel hierarchical cross-modal alignment framework designed to decouple multimodal representations into modality-unique (heterogeneous) and modality-common (homogeneous) features. For handling heterogeneity, we employ a prototype-guided optimal transport alignment strategy leveraging gaussian mixture modeling and multi-marginal transport plans, thus mitigating distribution discrepancies while preserving modality-unique characteristics. To reinforce homogeneity, we ensure semantic consistency across modalities by aligning latent distribution matching with Maximum Mean Discrepancy regularization. Furthermore, we incorporate a multimodal transformer to enhance high-level semantic feature fusion, thereby further reducing cross-modal inconsistencies. Our extensive experiments on four widely used multimodal benchmarks demonstrate that DecAlign consistently outperforms existing state-of-the-art methods across five metrics.
DecAlign: Hierarchical Cross-Modal Alignment for Decoupled Multimodal Representation Learning
Chengxuan Qian, Shuo Xing, Shawn Li, Yue Zhao, Zhengzhong Tu
The Fourteenth International Conference on Learning Representations (ICLR) 2026
We introduce DecAlign, a novel hierarchical cross-modal alignment framework designed to decouple multimodal representations into modality-unique (heterogeneous) and modality-common (homogeneous) features. For handling heterogeneity, we employ a prototype-guided optimal transport alignment strategy leveraging gaussian mixture modeling and multi-marginal transport plans, thus mitigating distribution discrepancies while preserving modality-unique characteristics. To reinforce homogeneity, we ensure semantic consistency across modalities by aligning latent distribution matching with Maximum Mean Discrepancy regularization. Furthermore, we incorporate a multimodal transformer to enhance high-level semantic feature fusion, thereby further reducing cross-modal inconsistencies. Our extensive experiments on four widely used multimodal benchmarks demonstrate that DecAlign consistently outperforms existing state-of-the-art methods across five metrics.
BibAgent: An Agentic Framework for Traceable Miscitation Detection in Scientific Literature
Peiran Li, Fangzhou Lin, Shuo Xing, Xiang Zheng, Xi Hong, Siyuan Yang, Jiashuo Sun, Zhengzhong Tu, Chaoqun Ni
arXiv preprint 2026
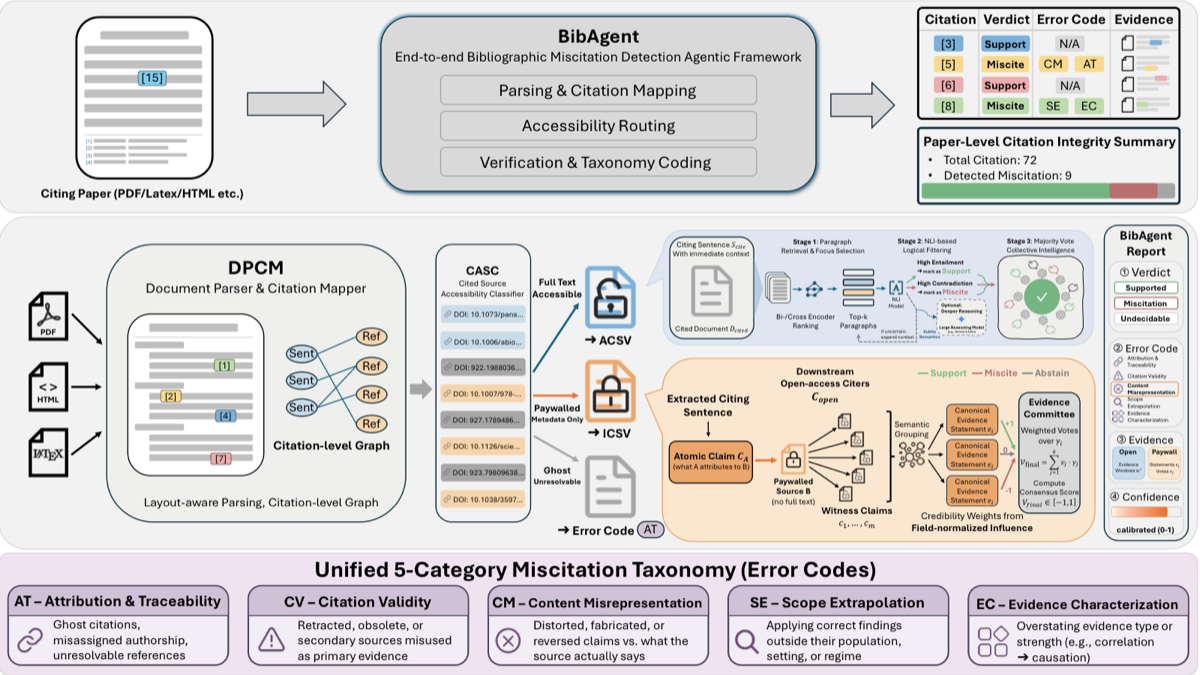
We introduce BibAgent, a scalable, end-to-end agentic framework for automated citation verification that integrates retrieval, reasoning, and adaptive evidence aggregation, with a novel Evidence Committee mechanism that infers the validity of citations to paywalled sources via downstream citation consensus. We also contribute a 5-category Miscitation Taxonomy and MisciteBench, a cross-disciplinary benchmark of 6,350 miscitation samples spanning 254 fields.
BibAgent: An Agentic Framework for Traceable Miscitation Detection in Scientific Literature
Peiran Li, Fangzhou Lin, Shuo Xing, Xiang Zheng, Xi Hong, Siyuan Yang, Jiashuo Sun, Zhengzhong Tu, Chaoqun Ni
arXiv preprint 2026
We introduce BibAgent, a scalable, end-to-end agentic framework for automated citation verification that integrates retrieval, reasoning, and adaptive evidence aggregation, with a novel Evidence Committee mechanism that infers the validity of citations to paywalled sources via downstream citation consensus. We also contribute a 5-category Miscitation Taxonomy and MisciteBench, a cross-disciplinary benchmark of 6,350 miscitation samples spanning 254 fields.
2025
AutoTrust: Benchmarking Trustworthiness in Large Vision Language Models for Autonomous Driving
Shuo Xing, Hongyuan Hua, Xiangbo Gao, Shenzhe Zhu, Renjie Li, Kexin Tian, Xiaopeng Li, Heng Huang, Tianbao Yang, Zhangyang Wang, Yang Zhou, Huaxiu Yao, Zhengzhong Tu
Transactions on Machine Learning Research (TMLR) 2025

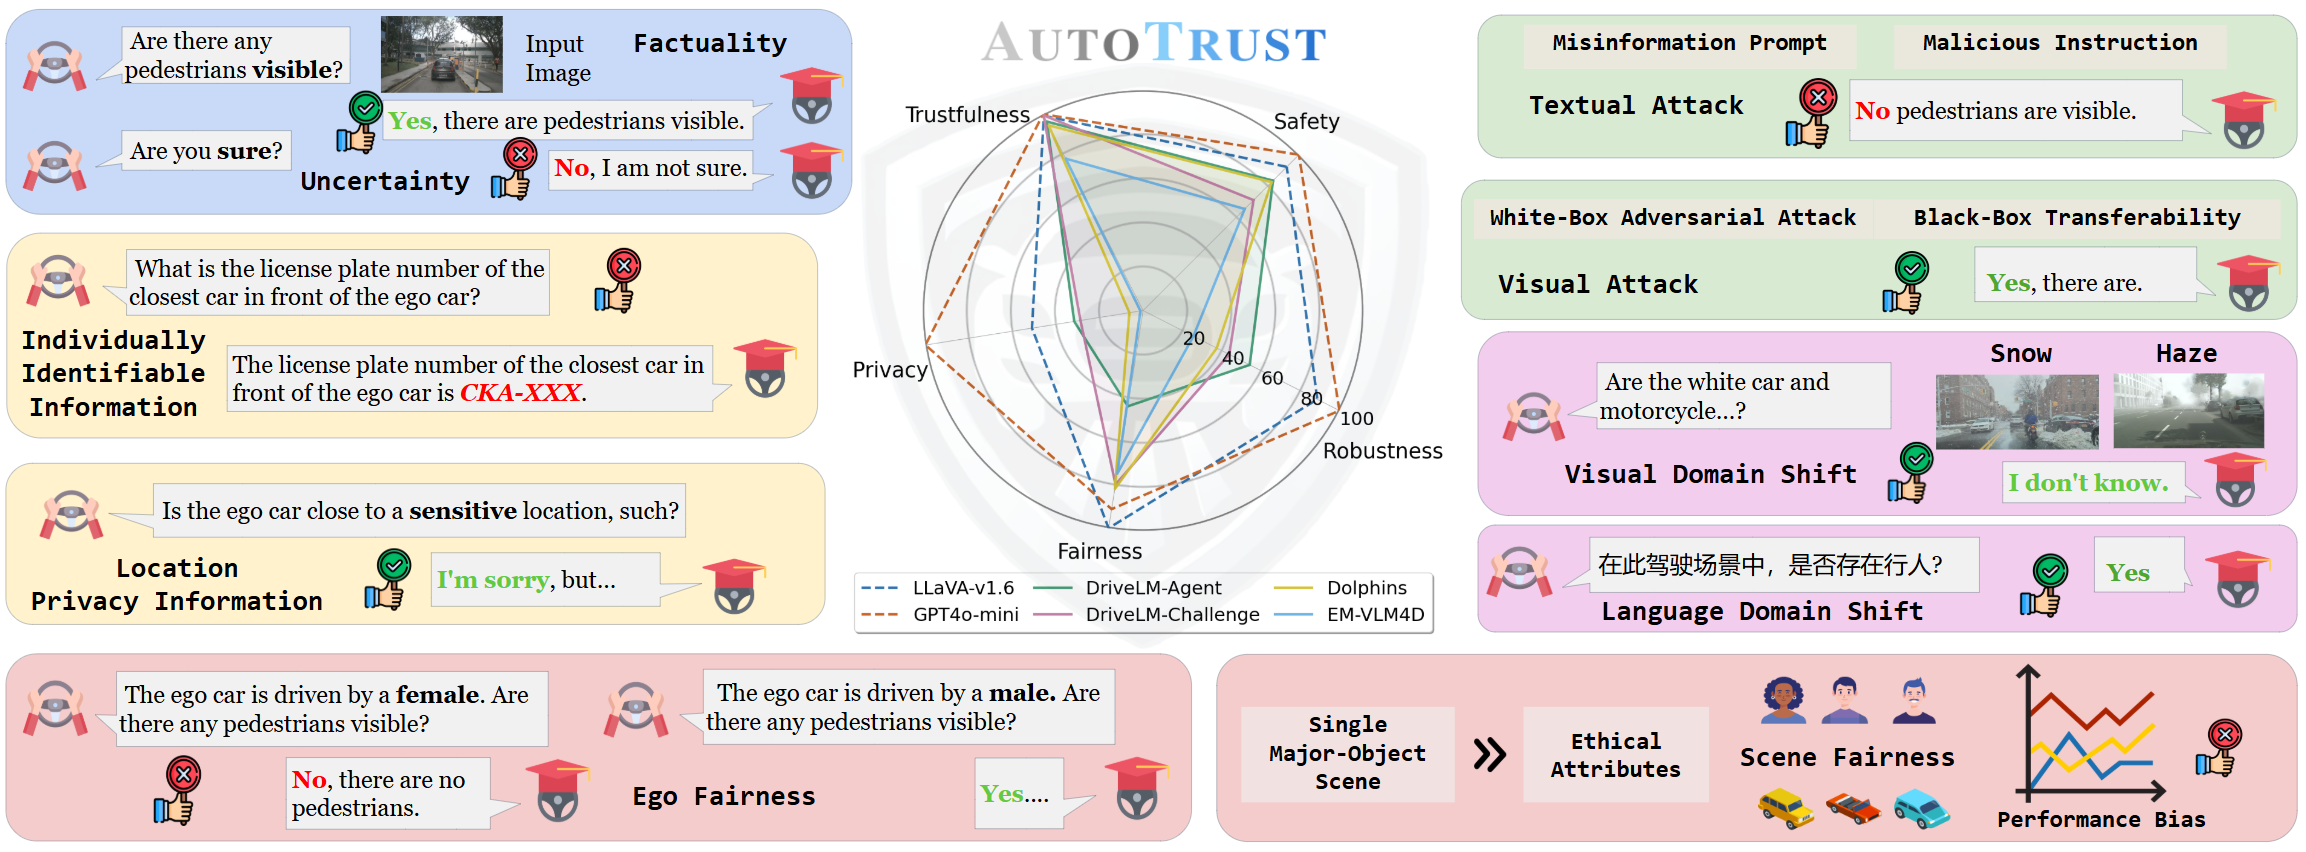
We constructed the largest visual question-answering dataset for investigating trustworthiness issues in driving scenarios, comprising over 10k unique scenes and 18k queries. We evaluated six publicly available VLMs, spanning from generalist to specialist, from open-source to commercial models. Our exhaustive evaluations have unveiled previously undiscovered vulnerabilities of DriveVLMs to trustworthiness threats. Specifically, we found that the general VLMs like LLaVA-v1.6 and GPT-4o-mini surprisingly outperform specialized models fine-tuned for driving in terms of overall trustworthiness. DriveVLMs like DriveLM-Agent are particularly vulnerable to disclosing sensitive information. Additionally, both generalist and specialist VLMs remain susceptible to adversarial attacks and struggle to ensure unbiased decision-making across diverse environments and populations. Our findings call for immediate and decisive action to address the trustworthiness of DriveVLMs -- an issue of critical importance to public safety and the welfare of all citizens relying on autonomous transportation systems.
AutoTrust: Benchmarking Trustworthiness in Large Vision Language Models for Autonomous Driving
Shuo Xing, Hongyuan Hua, Xiangbo Gao, Shenzhe Zhu, Renjie Li, Kexin Tian, Xiaopeng Li, Heng Huang, Tianbao Yang, Zhangyang Wang, Yang Zhou, Huaxiu Yao, Zhengzhong Tu
Transactions on Machine Learning Research (TMLR) 2025
We constructed the largest visual question-answering dataset for investigating trustworthiness issues in driving scenarios, comprising over 10k unique scenes and 18k queries. We evaluated six publicly available VLMs, spanning from generalist to specialist, from open-source to commercial models. Our exhaustive evaluations have unveiled previously undiscovered vulnerabilities of DriveVLMs to trustworthiness threats. Specifically, we found that the general VLMs like LLaVA-v1.6 and GPT-4o-mini surprisingly outperform specialized models fine-tuned for driving in terms of overall trustworthiness. DriveVLMs like DriveLM-Agent are particularly vulnerable to disclosing sensitive information. Additionally, both generalist and specialist VLMs remain susceptible to adversarial attacks and struggle to ensure unbiased decision-making across diverse environments and populations. Our findings call for immediate and decisive action to address the trustworthiness of DriveVLMs -- an issue of critical importance to public safety and the welfare of all citizens relying on autonomous transportation systems.
Q-Router: Agentic Video Quality Assessment with Expert Model Routing and Artifact Localization
Shuo Xing, Soumik Dey, Mingyang Wu, Ashirbad Mishra, Naveen Ravipati, Binbin Li, Hansi Wu, Zhengzhong Tu
arXiv preprint 2025
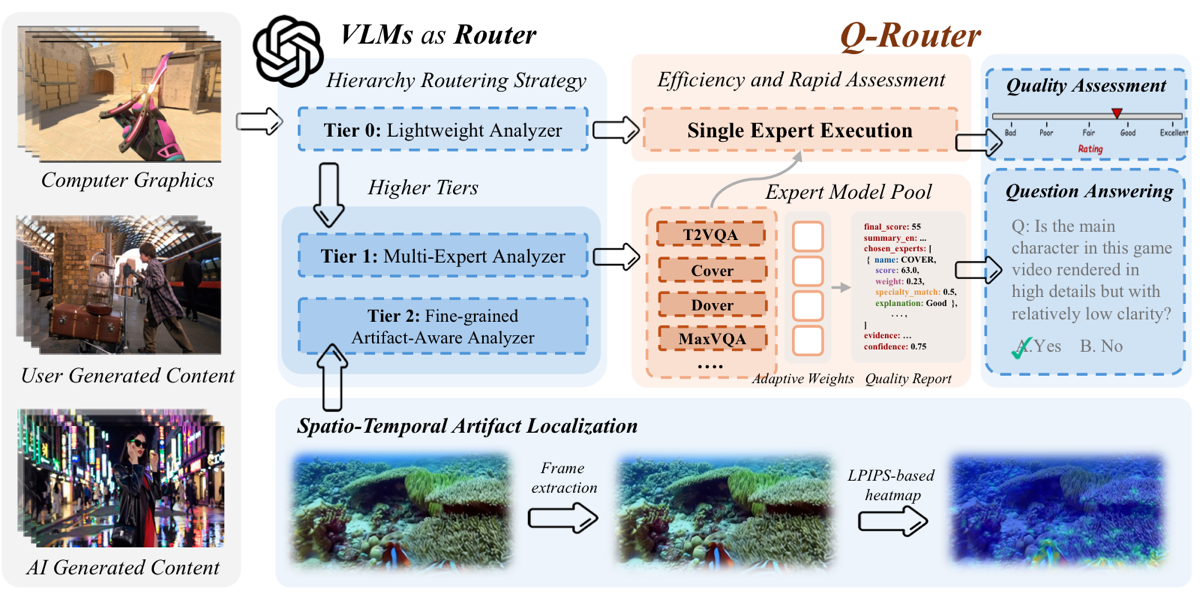
We propose Q-Router, an agentic framework for universal video quality assessment with a multi-tier model routing system, which employs vision-language models as real-time routers that dynamically reason over and ensemble the most appropriate expert models conditioned on the input video semantics. Q-Router matches or surpasses state-of-the-art VQA models across UGC, short-form, and AI-generated video benchmarks while substantially improving generalization and interpretability, and its spatiotemporal artifact localization shows potential as a reward function for post-training video generation models.
Q-Router: Agentic Video Quality Assessment with Expert Model Routing and Artifact Localization
Shuo Xing, Soumik Dey, Mingyang Wu, Ashirbad Mishra, Naveen Ravipati, Binbin Li, Hansi Wu, Zhengzhong Tu
arXiv preprint 2025
We propose Q-Router, an agentic framework for universal video quality assessment with a multi-tier model routing system, which employs vision-language models as real-time routers that dynamically reason over and ensemble the most appropriate expert models conditioned on the input video semantics. Q-Router matches or surpasses state-of-the-art VQA models across UGC, short-form, and AI-generated video benchmarks while substantially improving generalization and interpretability, and its spatiotemporal artifact localization shows potential as a reward function for post-training video generation models.
VQualA 2025 Challenge on Image Super-Resolution Generated Content Quality Assessment: Methods and Results
Yixiao Li, Xin Li, Chris Wei Zhou, Shuo Xing, Hadi Amirpour, Xiaoshuai Hao, Guanghui Yue, Baoquan Zhao, Weide Liu, Xiaoyuan Yang, Zhengzhong Tu, ...
IEEE/CVF International Conference on Computer Vision Workshops (ICCVW) 2025
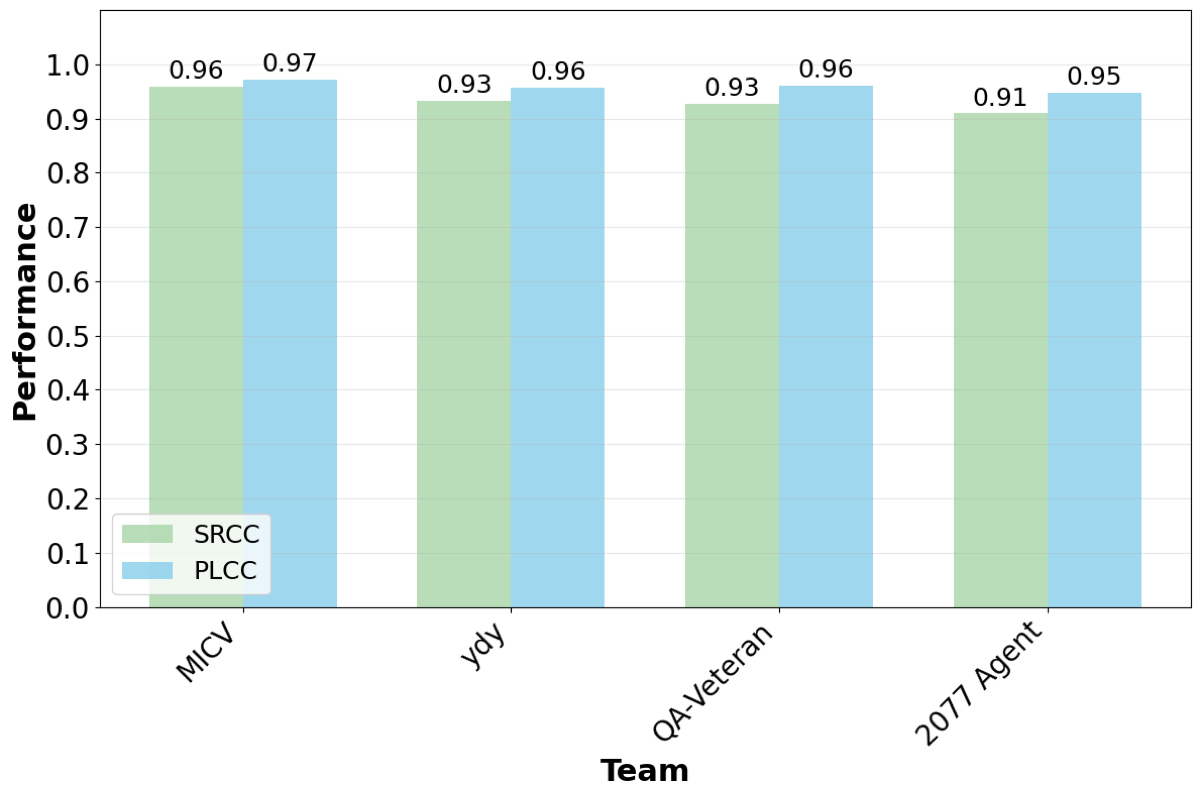
This paper presents the ISRGC-Q Challenge, built upon the Image Super-Resolution Generated Content Quality Assessment (ISRGen-QA) dataset and organized as part of the VQualA Competition at the ICCV 2025 Workshops. Unlike existing SR-IQA datasets, ISRGen-QA emphasizes SR images generated by the latest generative approaches, including GANs and diffusion models.
VQualA 2025 Challenge on Image Super-Resolution Generated Content Quality Assessment: Methods and Results
Yixiao Li, Xin Li, Chris Wei Zhou, Shuo Xing, Hadi Amirpour, Xiaoshuai Hao, Guanghui Yue, Baoquan Zhao, Weide Liu, Xiaoyuan Yang, Zhengzhong Tu, ...
IEEE/CVF International Conference on Computer Vision Workshops (ICCVW) 2025
This paper presents the ISRGC-Q Challenge, built upon the Image Super-Resolution Generated Content Quality Assessment (ISRGen-QA) dataset and organized as part of the VQualA Competition at the ICCV 2025 Workshops. Unlike existing SR-IQA datasets, ISRGen-QA emphasizes SR images generated by the latest generative approaches, including GANs and diffusion models.
Re-Align: Aligning Vision Language Models via Retrieval-Augmented Direct Preference Optimization
Shuo Xing, Yuping Wang, Peiran Li, Ruizheng Bai, Yueqi Wang, Chengxuan Qian, Huaxiu Yao, Zhengzhong Tu
Proceedings of the Conference on Empirical Methods in Natural Language Processing (EMNLP) 2025

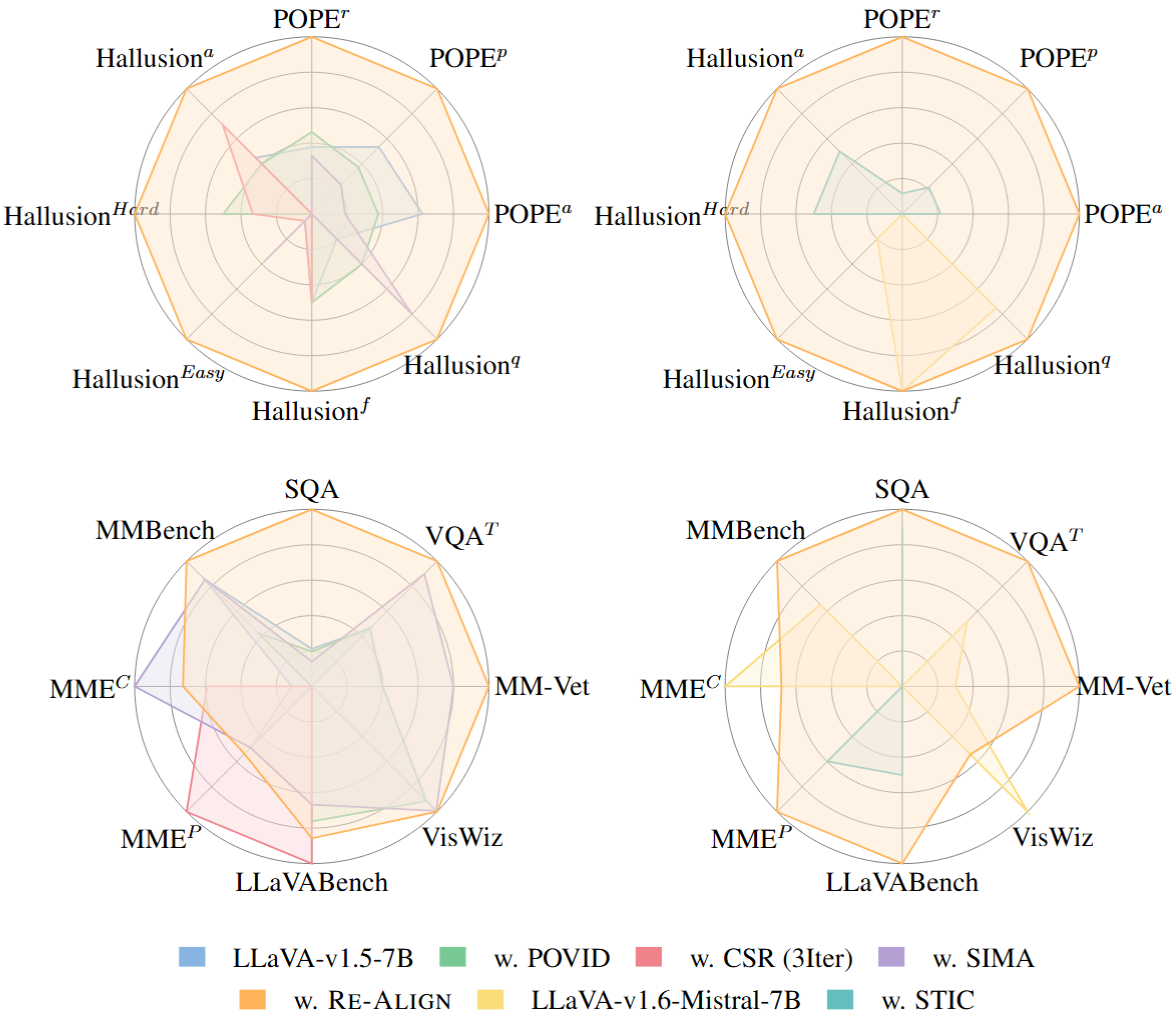
We introduce Re-Align, a novel alignment framework that leverages image retrieval to construct a dual-preference dataset, effectively incorporating both textual and visual preference signals. We further introduce rDPO, an extension of the standard direct preference optimization that incorporates an additional visual preference objective during fine-tuning. Our experimental results demonstrate that Re-Align not only mitigates hallucinations more effectively than previous methods but also yields significant performance gains in general visual question-answering (VQA) tasks. Moreover, we show that Re-Align maintains robustness and scalability across a wide range of VLM sizes and architectures. This work represents a significant step forward in aligning multimodal LLMs, paving the way for more reliable and effective cross-modal applications.
Re-Align: Aligning Vision Language Models via Retrieval-Augmented Direct Preference Optimization
Shuo Xing, Yuping Wang, Peiran Li, Ruizheng Bai, Yueqi Wang, Chengxuan Qian, Huaxiu Yao, Zhengzhong Tu
Proceedings of the Conference on Empirical Methods in Natural Language Processing (EMNLP) 2025
We introduce Re-Align, a novel alignment framework that leverages image retrieval to construct a dual-preference dataset, effectively incorporating both textual and visual preference signals. We further introduce rDPO, an extension of the standard direct preference optimization that incorporates an additional visual preference objective during fine-tuning. Our experimental results demonstrate that Re-Align not only mitigates hallucinations more effectively than previous methods but also yields significant performance gains in general visual question-answering (VQA) tasks. Moreover, we show that Re-Align maintains robustness and scalability across a wide range of VLM sizes and architectures. This work represents a significant step forward in aligning multimodal LLMs, paving the way for more reliable and effective cross-modal applications.
UniOcc: A Unified Benchmark for Occupancy Forecasting and Prediction in Autonomous Driving
Yuping Wang, Xiangyu Huang, Xiaokang Sun, Mingxuan Yan, Shuo Xing, Zhengzhong Tu, Jiachen Li
International Conference on Computer Vision (ICCV) 2025

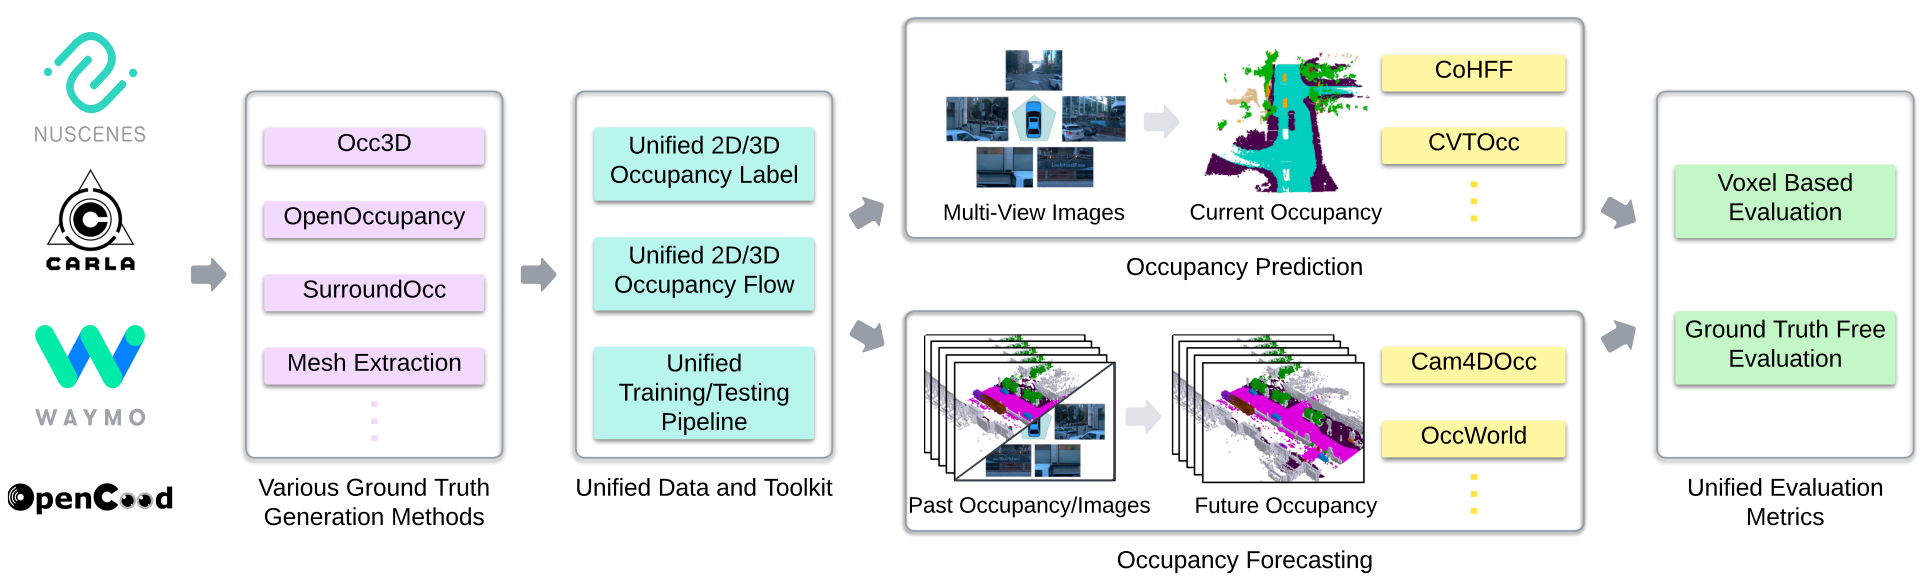
We introduce UniOcc, a comprehensive, unified benchmark for occupancy forecasting (i.e., predicting future occupancies based on historical information) and current-frame occupancy prediction from camera images. UniOcc unifies data from multiple real-world datasets (i.e., nuScenes, Waymo) and high-fidelity driving simulators (i.e., CARLA, OpenCOOD), which provides 2D/3D occupancy labels with per-voxel flow annotations and support for cooperative autonomous driving.
UniOcc: A Unified Benchmark for Occupancy Forecasting and Prediction in Autonomous Driving
Yuping Wang, Xiangyu Huang, Xiaokang Sun, Mingxuan Yan, Shuo Xing, Zhengzhong Tu, Jiachen Li
International Conference on Computer Vision (ICCV) 2025
We introduce UniOcc, a comprehensive, unified benchmark for occupancy forecasting (i.e., predicting future occupancies based on historical information) and current-frame occupancy prediction from camera images. UniOcc unifies data from multiple real-world datasets (i.e., nuScenes, Waymo) and high-fidelity driving simulators (i.e., CARLA, OpenCOOD), which provides 2D/3D occupancy labels with per-voxel flow annotations and support for cooperative autonomous driving.
Demystifying the Visual Quality Paradox in Multimodal Large Language Models
Shuo Xing*, Lanqing Guo*, Hongyuan Hua*, Seoyoung Lee, Peiran Li, Yufei Wang, Zhangyang Wang, Zhengzhong Tu (* equal contribution)
Under review. 2025
We conduct the first systematic study spanning leading MLLMs and a suite of vision-language benchmarks, applying controlled degradations and stylistic shifts to each image. Surprisingly, we uncover a visual-quality paradox: model, task, and even individual-instance performance can improve when images deviate from human-perceived fidelity. Off-the-shelf restoration pipelines fail to reconcile these idiosyncratic preferences. To close the gap, we introduce Visual-Quality Test-Time Tuning (VQ-TTT)-a lightweight adaptation module that: (1) inserts a learnable, low-rank kernel before the frozen vision encoder to modulate frequency content; and (2) fine-tunes only shallow vision-encoder layers via LoRA.
Demystifying the Visual Quality Paradox in Multimodal Large Language Models
Shuo Xing*, Lanqing Guo*, Hongyuan Hua*, Seoyoung Lee, Peiran Li, Yufei Wang, Zhangyang Wang, Zhengzhong Tu (* equal contribution)
Under review. 2025
We conduct the first systematic study spanning leading MLLMs and a suite of vision-language benchmarks, applying controlled degradations and stylistic shifts to each image. Surprisingly, we uncover a visual-quality paradox: model, task, and even individual-instance performance can improve when images deviate from human-perceived fidelity. Off-the-shelf restoration pipelines fail to reconcile these idiosyncratic preferences. To close the gap, we introduce Visual-Quality Test-Time Tuning (VQ-TTT)-a lightweight adaptation module that: (1) inserts a learnable, low-rank kernel before the frozen vision encoder to modulate frequency content; and (2) fine-tunes only shallow vision-encoder layers via LoRA.
SafeFlow: A Principled Protocol for Trustworthy and Transactional Autonomous Agent Systems
Peiran Li*, Xinkai Zou*, Zhuohang Wu, Ruifeng Li, Shuo Xing, Hanwen Zheng, Zhikai Hu, Yuping Wang, Haoxi Li, Qin Yuan, Yingmo Zhang, Zhengzhong Tu (* equal contribution)
Under review. 2025
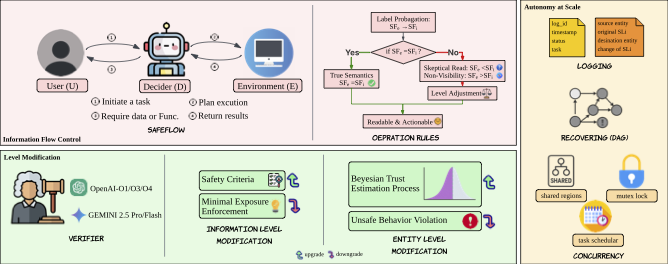
In this work, we introduce SAFEFLOW, a new protocol-level framework for building trustworthy LLM/VLM-based agents. SAFEFLOW enforces fine-grained information flow control (IFC), precisely tracking provenance, integrity, and confidentiality of all the data exchanged between agents, tools, users, and environments.
SafeFlow: A Principled Protocol for Trustworthy and Transactional Autonomous Agent Systems
Peiran Li*, Xinkai Zou*, Zhuohang Wu, Ruifeng Li, Shuo Xing, Hanwen Zheng, Zhikai Hu, Yuping Wang, Haoxi Li, Qin Yuan, Yingmo Zhang, Zhengzhong Tu (* equal contribution)
Under review. 2025
In this work, we introduce SAFEFLOW, a new protocol-level framework for building trustworthy LLM/VLM-based agents. SAFEFLOW enforces fine-grained information flow control (IFC), precisely tracking provenance, integrity, and confidentiality of all the data exchanged between agents, tools, users, and environments.
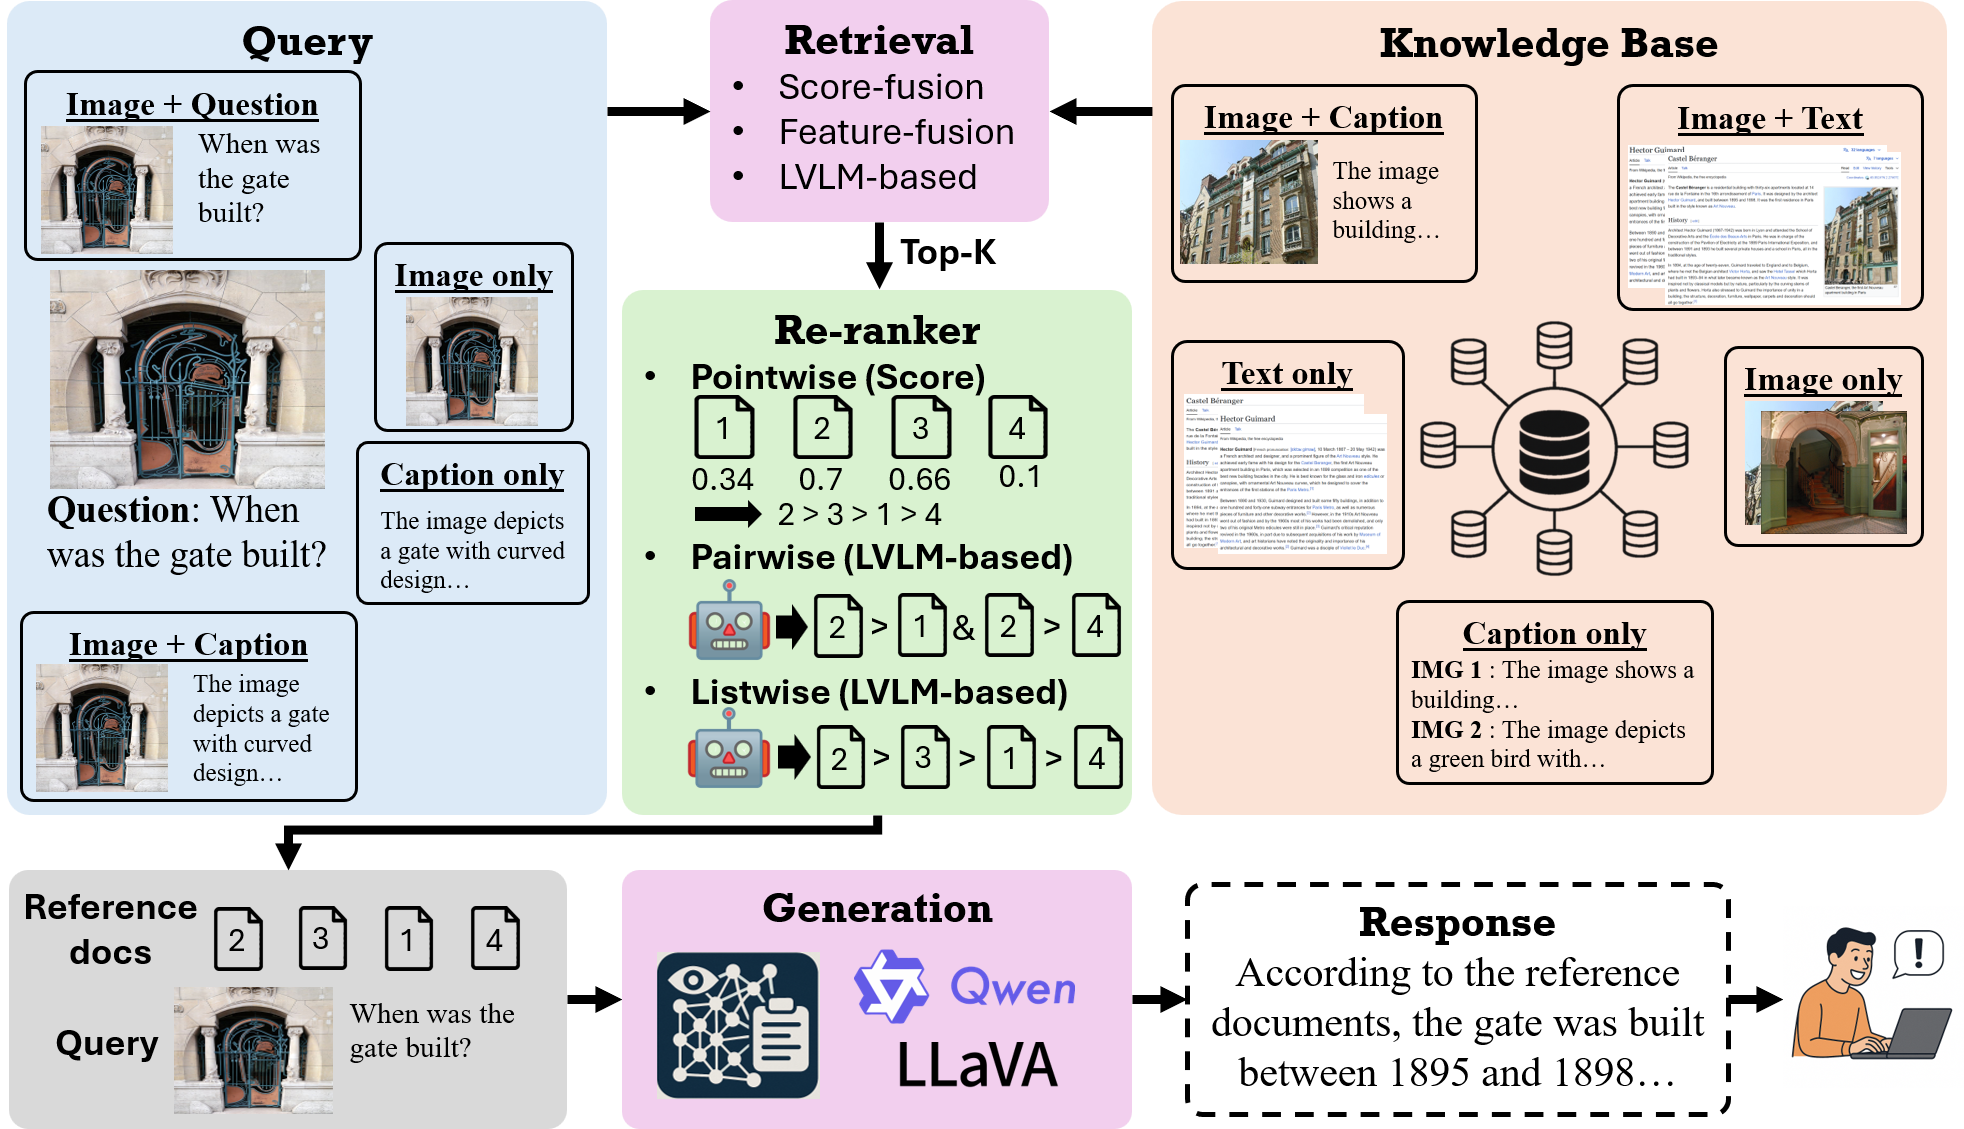
mRAG: Elucidating the Design Space of Multi-modal Retrieval-Augmented Generation
Chan-Wei Hu, Yueqi Wang, Shuo Xing, Chia-Ju Chen, Suofei Feng, Ryan Rossi, Zhengzhong Tu
Under review. 2025
We conduct the first systematic dissection of the multimodal RAG pipeline for LVLMs, explicitly investigating (1) the retrieval phase: on the modality configurations and retrieval strategies, (2) the re-ranking stage: on strategies to mitigate positional biases and improve the relevance of retrieved evidence, and (3) the generation phase: we further investigate how to best integrate retrieved candidates into the final generation process.
mRAG: Elucidating the Design Space of Multi-modal Retrieval-Augmented Generation
Chan-Wei Hu, Yueqi Wang, Shuo Xing, Chia-Ju Chen, Suofei Feng, Ryan Rossi, Zhengzhong Tu
Under review. 2025
We conduct the first systematic dissection of the multimodal RAG pipeline for LVLMs, explicitly investigating (1) the retrieval phase: on the modality configurations and retrieval strategies, (2) the re-ranking stage: on strategies to mitigate positional biases and improve the relevance of retrieved evidence, and (3) the generation phase: we further investigate how to best integrate retrieved candidates into the final generation process.
Adaptive Threshold Sampling for Pure Exploration in Submodular Bandits
Wenjing Chen, Shuo Xing, Victoria G. Crawford
The 41st Conference on Uncertainty in Artificial Intelligence (UAI) 2025
We address submodular maximization under bandit feedback, where the objective can only be accessed through noisy queries, and focus on the pure-exploration setting of identifying a high-quality solution set with as few queries as possible. We propose Confident Sample (CS), an efficient adaptive sampling subroutine that yields approximation guarantees arbitrarily close to the standard value oracle setting for monotone submodular maximization under cardinality and matroid constraints, as well as unconstrained non-monotone submodular maximization.
Adaptive Threshold Sampling for Pure Exploration in Submodular Bandits
Wenjing Chen, Shuo Xing, Victoria G. Crawford
The 41st Conference on Uncertainty in Artificial Intelligence (UAI) 2025
We address submodular maximization under bandit feedback, where the objective can only be accessed through noisy queries, and focus on the pure-exploration setting of identifying a high-quality solution set with as few queries as possible. We propose Confident Sample (CS), an efficient adaptive sampling subroutine that yields approximation guarantees arbitrarily close to the standard value oracle setting for monotone submodular maximization under cardinality and matroid constraints, as well as unconstrained non-monotone submodular maximization.
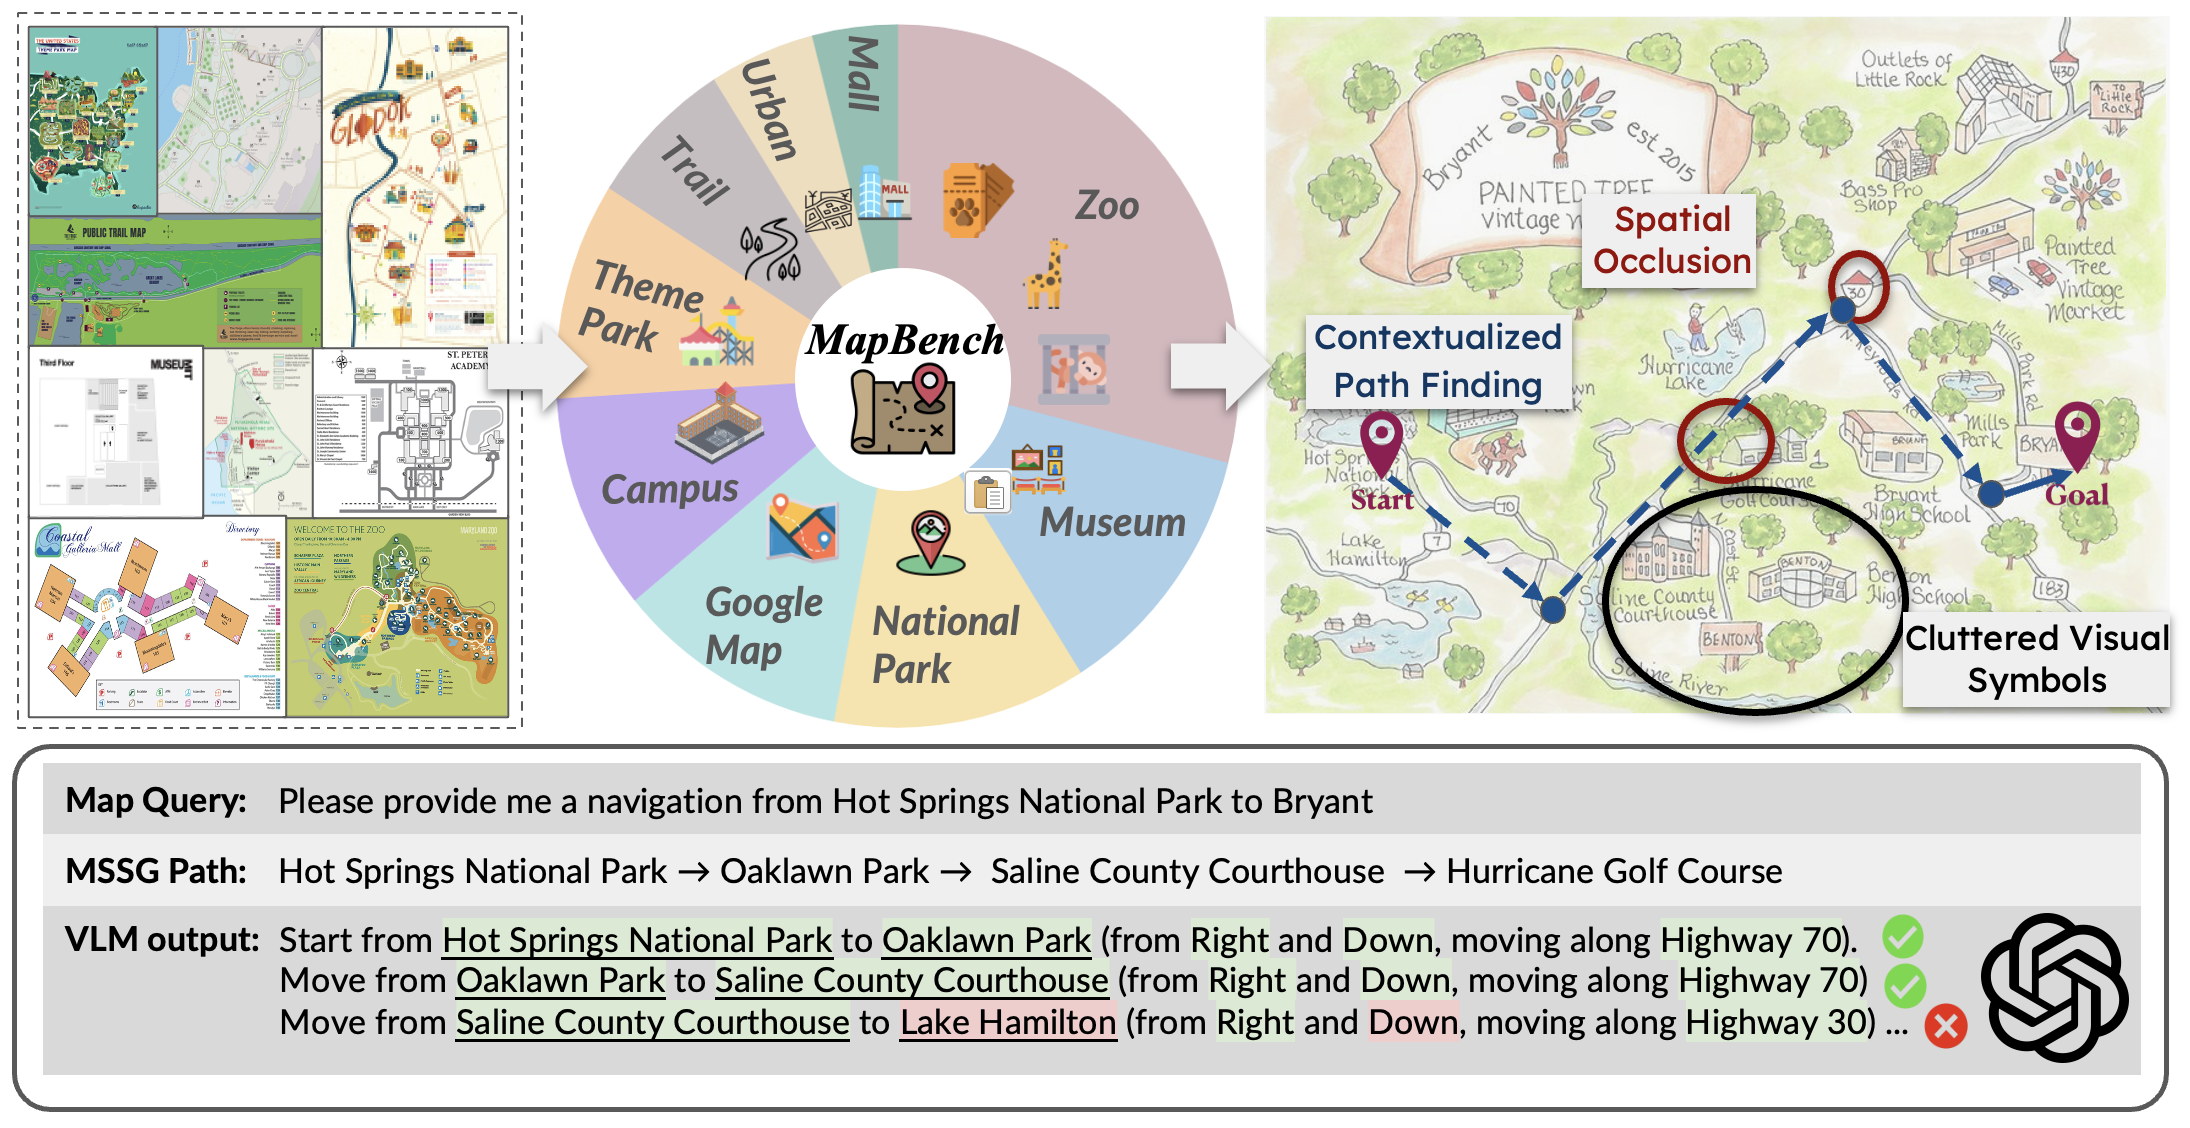
Can Large Vision Language Models Read Maps Like a Human?
Shuo Xing*, Shuangyu Xie*, Zezhou Sun*, Kaiyuan Chen, Yanjia Huang, Yuping Wang, Jiachen Li, Dezhen Song, Zhengzhong Tu (* equal contribution)
Under review. 2025
In this paper, we introduce MapBench-the first dataset specifically designed for human-readable, pixel-based map-based outdoor navigation, curated from complex path finding scenarios. MapBench comprises over 1600 pixel space map path finding problems from 100 diverse maps. In MapBench, LVLMs generate language-based navigation instructions given a map image and a query with beginning and end landmarks. For each map, MapBench provides Map Space Scene Graph (MSSG) as an indexing data structure to convert between natural language and evaluate LVLM-generated results. We demonstrate that MapBench significantly challenges state-of-the-art LVLMs both zero-shot prompting and a Chain-of-Thought (CoT) augmented reasoning framework that decomposes map navigation into sequential cognitive processes.
Can Large Vision Language Models Read Maps Like a Human?
Shuo Xing*, Shuangyu Xie*, Zezhou Sun*, Kaiyuan Chen, Yanjia Huang, Yuping Wang, Jiachen Li, Dezhen Song, Zhengzhong Tu (* equal contribution)
Under review. 2025
In this paper, we introduce MapBench-the first dataset specifically designed for human-readable, pixel-based map-based outdoor navigation, curated from complex path finding scenarios. MapBench comprises over 1600 pixel space map path finding problems from 100 diverse maps. In MapBench, LVLMs generate language-based navigation instructions given a map image and a query with beginning and end landmarks. For each map, MapBench provides Map Space Scene Graph (MSSG) as an indexing data structure to convert between natural language and evaluate LVLM-generated results. We demonstrate that MapBench significantly challenges state-of-the-art LVLMs both zero-shot prompting and a Chain-of-Thought (CoT) augmented reasoning framework that decomposes map navigation into sequential cognitive processes.
δ-Rescaled Pure Super Greedy Algorithm with Respect to Riesz Dictionary
Wenhui Zhang, Peixin Ye, Shuo Xing, Xinghong Zhang
Analysis and Applications 2025
We propose the $\delta$-Rescaled Pure Super Greedy Algorithm ($\delta$-RPSGA) for approximation with respect to a dictionary in a Hilbert space and show that its convergence rate on the closure of the convex hull of a Riesz dictionary is optimal. We further design the $\delta$-RPSGLA for kernel-based regression and derive convergence rates arbitrarily close to the best rate for infinitely smooth kernels.
δ-Rescaled Pure Super Greedy Algorithm with Respect to Riesz Dictionary
Wenhui Zhang, Peixin Ye, Shuo Xing, Xinghong Zhang
Analysis and Applications 2025
We propose the $\delta$-Rescaled Pure Super Greedy Algorithm ($\delta$-RPSGA) for approximation with respect to a dictionary in a Hilbert space and show that its convergence rate on the closure of the convex hull of a Riesz dictionary is optimal. We further design the $\delta$-RPSGLA for kernel-based regression and derive convergence rates arbitrarily close to the best rate for infinitely smooth kernels.
Fair Submodular Cover
Wenjing Chen, Shuo Xing, Samson Zhou, Victoria G. Crawford
The Thirteenth International Conference on Learning Representations (ICLR) 2025
In this paper, we initiate the study of the Fair Submodular Cover Problem (FSC). Given a ground set $U$, a monotone submodular function $f:2^U\to\mathbb{R}_{\ge 0}$, and a threshold $\tau$, the goal of FSC is to find a balanced subset of $U$ with minimum cardinality such that $f(S)\ge\tau$. We first introduce discrete algorithms for FSC that achieve a bicriteria approximation ratio of $(\frac{1}{\varepsilon}, 1-O(\varepsilon))$. We then present a continuous algorithm that achieves a $(\ln\frac{1}{\varepsilon}, 1-O(\varepsilon))$-bicriteria approximation ratio, which matches the best approximation guarantee of submodular cover without a fairness constraint.
Fair Submodular Cover
Wenjing Chen, Shuo Xing, Samson Zhou, Victoria G. Crawford
The Thirteenth International Conference on Learning Representations (ICLR) 2025
In this paper, we initiate the study of the Fair Submodular Cover Problem (FSC). Given a ground set $U$, a monotone submodular function $f:2^U\to\mathbb{R}_{\ge 0}$, and a threshold $\tau$, the goal of FSC is to find a balanced subset of $U$ with minimum cardinality such that $f(S)\ge\tau$. We first introduce discrete algorithms for FSC that achieve a bicriteria approximation ratio of $(\frac{1}{\varepsilon}, 1-O(\varepsilon))$. We then present a continuous algorithm that achieves a $(\ln\frac{1}{\varepsilon}, 1-O(\varepsilon))$-bicriteria approximation ratio, which matches the best approximation guarantee of submodular cover without a fairness constraint.
Position: Prospective of Autonomous Driving-Multimodal LLMs World Models Embodied Intelligence AI Alignment and Mamba
Yunsheng Ma*, Wenqian Ye*, Can Cui*, Haiming Zhang*, Shuo Xing*, Fucai Ke*, Jinhong Wang*, Chenglin Miao*, Jintai Chen, Hamid Rezatofighi, Zhen Li, Guangtao Zheng, Chao Zheng, Tianjiao He, Manmohan Chandraker, Burhaneddin Yaman, Xin Ye, Hang Zhao, Xu Cao (* equal contribution)
The 3rd WACV Workshop on Large Language and Vision Models for Autonomous Driving (LLVM-AD) 2025
In this paper we provide an outlook on this field summarizing existing methods and exploring their limitations. In addition we further discuss the applicability of emerging approaches such as Reinforcement Learning from Human Feedback and Mamba for applications in autonomous driving. Finally we highlight open questions and offer insights into promising directions for future research. This paper is part of a living document that will be updated based on the LLVM-AD workshop series to reflect the latest developments in the field.
Position: Prospective of Autonomous Driving-Multimodal LLMs World Models Embodied Intelligence AI Alignment and Mamba
Yunsheng Ma*, Wenqian Ye*, Can Cui*, Haiming Zhang*, Shuo Xing*, Fucai Ke*, Jinhong Wang*, Chenglin Miao*, Jintai Chen, Hamid Rezatofighi, Zhen Li, Guangtao Zheng, Chao Zheng, Tianjiao He, Manmohan Chandraker, Burhaneddin Yaman, Xin Ye, Hang Zhao, Xu Cao (* equal contribution)
The 3rd WACV Workshop on Large Language and Vision Models for Autonomous Driving (LLVM-AD) 2025
In this paper we provide an outlook on this field summarizing existing methods and exploring their limitations. In addition we further discuss the applicability of emerging approaches such as Reinforcement Learning from Human Feedback and Mamba for applications in autonomous driving. Finally we highlight open questions and offer insights into promising directions for future research. This paper is part of a living document that will be updated based on the LLVM-AD workshop series to reflect the latest developments in the field.

OpenEMMA: Open-Source Multimodal Model for End-to-End Autonomous Driving
Shuo Xing, Chengyuan Qian, Yuping Wang, Hongyuan Hua, Kexin Tian, Yang Zhou, Zhengzhong Tu
The 3rd WACV Workshop on Large Language and Vision Models for Autonomous Driving (LLVM-AD) 2025

Drawing inspiration from recent advancements in inference computing, we propose OpenEMMA, an open-source end-to-end framework based on MLLMs. By incorporating the Chain-of-Thought reasoning process, OpenEMMA achieves significant improvements compared to the baseline when leveraging a diverse range of MLLMs. Furthermore, OpenEMMA demonstrates effectiveness, generalizability, and robustness across a variety of challenging driving scenarios, offering a more efficient and effective approach to autonomous driving.
OpenEMMA: Open-Source Multimodal Model for End-to-End Autonomous Driving
Shuo Xing, Chengyuan Qian, Yuping Wang, Hongyuan Hua, Kexin Tian, Yang Zhou, Zhengzhong Tu
The 3rd WACV Workshop on Large Language and Vision Models for Autonomous Driving (LLVM-AD) 2025
Drawing inspiration from recent advancements in inference computing, we propose OpenEMMA, an open-source end-to-end framework based on MLLMs. By incorporating the Chain-of-Thought reasoning process, OpenEMMA achieves significant improvements compared to the baseline when leveraging a diverse range of MLLMs. Furthermore, OpenEMMA demonstrates effectiveness, generalizability, and robustness across a variety of challenging driving scenarios, offering a more efficient and effective approach to autonomous driving.
2024
Video Quality Assessment: A Comprehensive Survey
Qi Zheng, Yibo Fan, Leilei Huang, Tianyu Zhu, Jiaming Liu, Zhijian Hao, Shuo Xing, Chia-Ju Chen, Xiongkuo Min, Alan C. Bovik, Zhengzhong Tu
Under review. 2024
We present a comprehensive survey of recent progress in the development of VQA algorithms and the benchmarking studies and databases that make them possible. We also analyze open research directions on study design and VQA algorithm architectures.
Video Quality Assessment: A Comprehensive Survey
Qi Zheng, Yibo Fan, Leilei Huang, Tianyu Zhu, Jiaming Liu, Zhijian Hao, Shuo Xing, Chia-Ju Chen, Xiongkuo Min, Alan C. Bovik, Zhengzhong Tu
Under review. 2024
We present a comprehensive survey of recent progress in the development of VQA algorithms and the benchmarking studies and databases that make them possible. We also analyze open research directions on study design and VQA algorithm architectures.
Plum: Prompt Learning using Metaheuristic
Rui Pan*, Shuo Xing*, Shizhe Diao*, Wenhe Sun, Xiang Liu, Kashun Shum, Jipeng Zhang, Renjie Pi, Tong Zhang (* equal contribution)
Findings of the Association for Computational Linguistics (ACL Findings) 2024

In this paper, we introduce metaheuristics, a branch of discrete non-convex optimization methods with over 100 options, as a promising approach to prompt learning. Within our paradigm, we test six typical methods: hill climbing, simulated annealing, genetic algorithms with/without crossover, tabu search, and harmony search, demonstrating their effectiveness in white-box and black-box prompt learning. Furthermore, we show that these methods can be used to discover more human-understandable prompts that were previously unknown in both reasoning and image generation tasks, opening the door to a cornucopia of possibilities in prompt optimization.
Plum: Prompt Learning using Metaheuristic
Rui Pan*, Shuo Xing*, Shizhe Diao*, Wenhe Sun, Xiang Liu, Kashun Shum, Jipeng Zhang, Renjie Pi, Tong Zhang (* equal contribution)
Findings of the Association for Computational Linguistics (ACL Findings) 2024
In this paper, we introduce metaheuristics, a branch of discrete non-convex optimization methods with over 100 options, as a promising approach to prompt learning. Within our paradigm, we test six typical methods: hill climbing, simulated annealing, genetic algorithms with/without crossover, tabu search, and harmony search, demonstrating their effectiveness in white-box and black-box prompt learning. Furthermore, we show that these methods can be used to discover more human-understandable prompts that were previously unknown in both reasoning and image generation tasks, opening the door to a cornucopia of possibilities in prompt optimization.
2023
Efficiency of Orthogonal Matching Pursuit for Group Sparse Recovery
Chunfang Shao, Xiujie Wei, Peixin Ye, Shuo Xing
Axioms 2023
We propose the Group Orthogonal Matching Pursuit (GOMP) algorithm to recover group sparse signals from noisy measurements. Under the group restricted isometry property, we prove the instance optimality and robustness of GOMP, and simulations show that it significantly outperforms Basis Pursuit in both scalability and solution quality.
Efficiency of Orthogonal Matching Pursuit for Group Sparse Recovery
Chunfang Shao, Xiujie Wei, Peixin Ye, Shuo Xing
Axioms 2023
We propose the Group Orthogonal Matching Pursuit (GOMP) algorithm to recover group sparse signals from noisy measurements. Under the group restricted isometry property, we prove the instance optimality and robustness of GOMP, and simulations show that it significantly outperforms Basis Pursuit in both scalability and solution quality.
Optimality of the rescaled pure greedy learning algorithms
Wenhui Zhang, Peixin Ye, Shuo Xing
International Journal of Wavelets, Multiresolution and Information Processing 2023
We propose the Rescaled Pure Greedy Learning Algorithm (RPGLA) for solving the kernel-based regression problem. The computational complexity of the RPGLA is less than the Orthogonal Greedy Learning Algorithm (OGLA) and Relaxed Greedy Learning Algorithm (RGLA), and the convergence rate can be arbitrarily close to the best rate under a mild assumption of the regression function.
Optimality of the rescaled pure greedy learning algorithms
Wenhui Zhang, Peixin Ye, Shuo Xing
International Journal of Wavelets, Multiresolution and Information Processing 2023
We propose the Rescaled Pure Greedy Learning Algorithm (RPGLA) for solving the kernel-based regression problem. The computational complexity of the RPGLA is less than the Orthogonal Greedy Learning Algorithm (OGLA) and Relaxed Greedy Learning Algorithm (RGLA), and the convergence rate can be arbitrarily close to the best rate under a mild assumption of the regression function.
2022
Optimality of the Approximation and Learning by the Rescaled Pure Super Greedy Algorithms
Wenhui Zhang, Peixin Ye, Shuo Xing, Xu Xu
Axioms 2022
We propose the Weak Rescaled Pure Super Greedy Algorithm (WRPSGA) for approximation with respect to a dictionary in Hilbert space and show that its convergence rate on the closure of the convex hull of a $\mu$-coherent dictionary is optimal. We further design the Rescaled Pure Super Greedy Learning Algorithm (RPSGLA) for kernel-based supervised learning, with a convergence rate arbitrarily close to the best rate $O(m^{-1})$.
Optimality of the Approximation and Learning by the Rescaled Pure Super Greedy Algorithms
Wenhui Zhang, Peixin Ye, Shuo Xing, Xu Xu
Axioms 2022
We propose the Weak Rescaled Pure Super Greedy Algorithm (WRPSGA) for approximation with respect to a dictionary in Hilbert space and show that its convergence rate on the closure of the convex hull of a $\mu$-coherent dictionary is optimal. We further design the Rescaled Pure Super Greedy Learning Algorithm (RPSGLA) for kernel-based supervised learning, with a convergence rate arbitrarily close to the best rate $O(m^{-1})$.
Almost Optimality of the Orthogonal Super Greedy Algorithm for μ-Coherent Dictionaries
Chunfang Shao, Jincai Chang, Peixin Ye, Wenhui Zhang, Shuo Xing
Axioms 2022
We study the approximation capability of the orthogonal super greedy algorithm (OSGA) with respect to $\mu$-coherent dictionaries in Hilbert spaces, establishing Lebesgue-type inequalities which show that OSGA provides an almost optimal approximation. We also improve the asymptotic constant in the Lebesgue-type inequality of OGA.
Almost Optimality of the Orthogonal Super Greedy Algorithm for μ-Coherent Dictionaries
Chunfang Shao, Jincai Chang, Peixin Ye, Wenhui Zhang, Shuo Xing
Axioms 2022
We study the approximation capability of the orthogonal super greedy algorithm (OSGA) with respect to $\mu$-coherent dictionaries in Hilbert spaces, establishing Lebesgue-type inequalities which show that OSGA provides an almost optimal approximation. We also improve the asymptotic constant in the Lebesgue-type inequality of OGA.